Optotypes? No, Optician Sans!
0. Introduction
If you ended up here, you probably heard about Optician Sans. I mean, it’s everywhere, from Fast Company to Gizmodo, introducing me to the experience of finding time to do e-mail and podcast interviews. I have even considered turning Behance notifications off, due to the constant phone buzzing (yes, I have now turned the vibration off for notifications – #smartFábio).
If this sounds snobberish, arrogant and ungrateful, it’s quite the contrary: I am flabbergast about how this came to be: all of this attention was completely unexpected to me.
Part storytelling, part making of, part as an outlet to process this phenomenon, I’m writing this so I can tell you what this typeface is and how it came to be in a degree of detail that I couldn’t do otherwise.
Alright, let’s do this!
1. The Backstory
1.1 Hello Reddit! Hello Simen!
After Optician Sans’ release into the wilderness that is the Internet, during a videocall to plan some stuff, I asked Simen Schikulski how he found me.
Simen is a gentle person, soft spoken and with dreamy eyes, that – once the conversation gets going – unveals his excitement and inner drive from his quiet demeanour. And he happens to work at ANTI Hamar, the Norwegian studio that commissioned me the production of Optician Sans – in fact, he was the person who started the typeface.
It was on Reddit: you offered me help to finish the typeface!, he told me. I had completely forgotten about it.
Simen’s post on /r/typography caught my eye for two reasons: first, I usually go around the subreddit to help people out; second, because it was about optotypes – at that time, I was researching about it myself to produce materials for my Masters’ students.
2. Optotypes
2.1 Optotypes?
Hold on, what’s an optotype? Right.
According to the Merriam-Webster entry on optotype, we have the following definition:
Optotype: figures or letters of different sizes used in testing the acuity of vision — usually used in plural.
Even if you are in no need of glasses — and unless you live in North Sentinel Island (how did you get an Internet connection over there, by the way?) — the chances are that you’ve had several close encounters with optotypes, most likely through a Snellen or LogMAR chart.
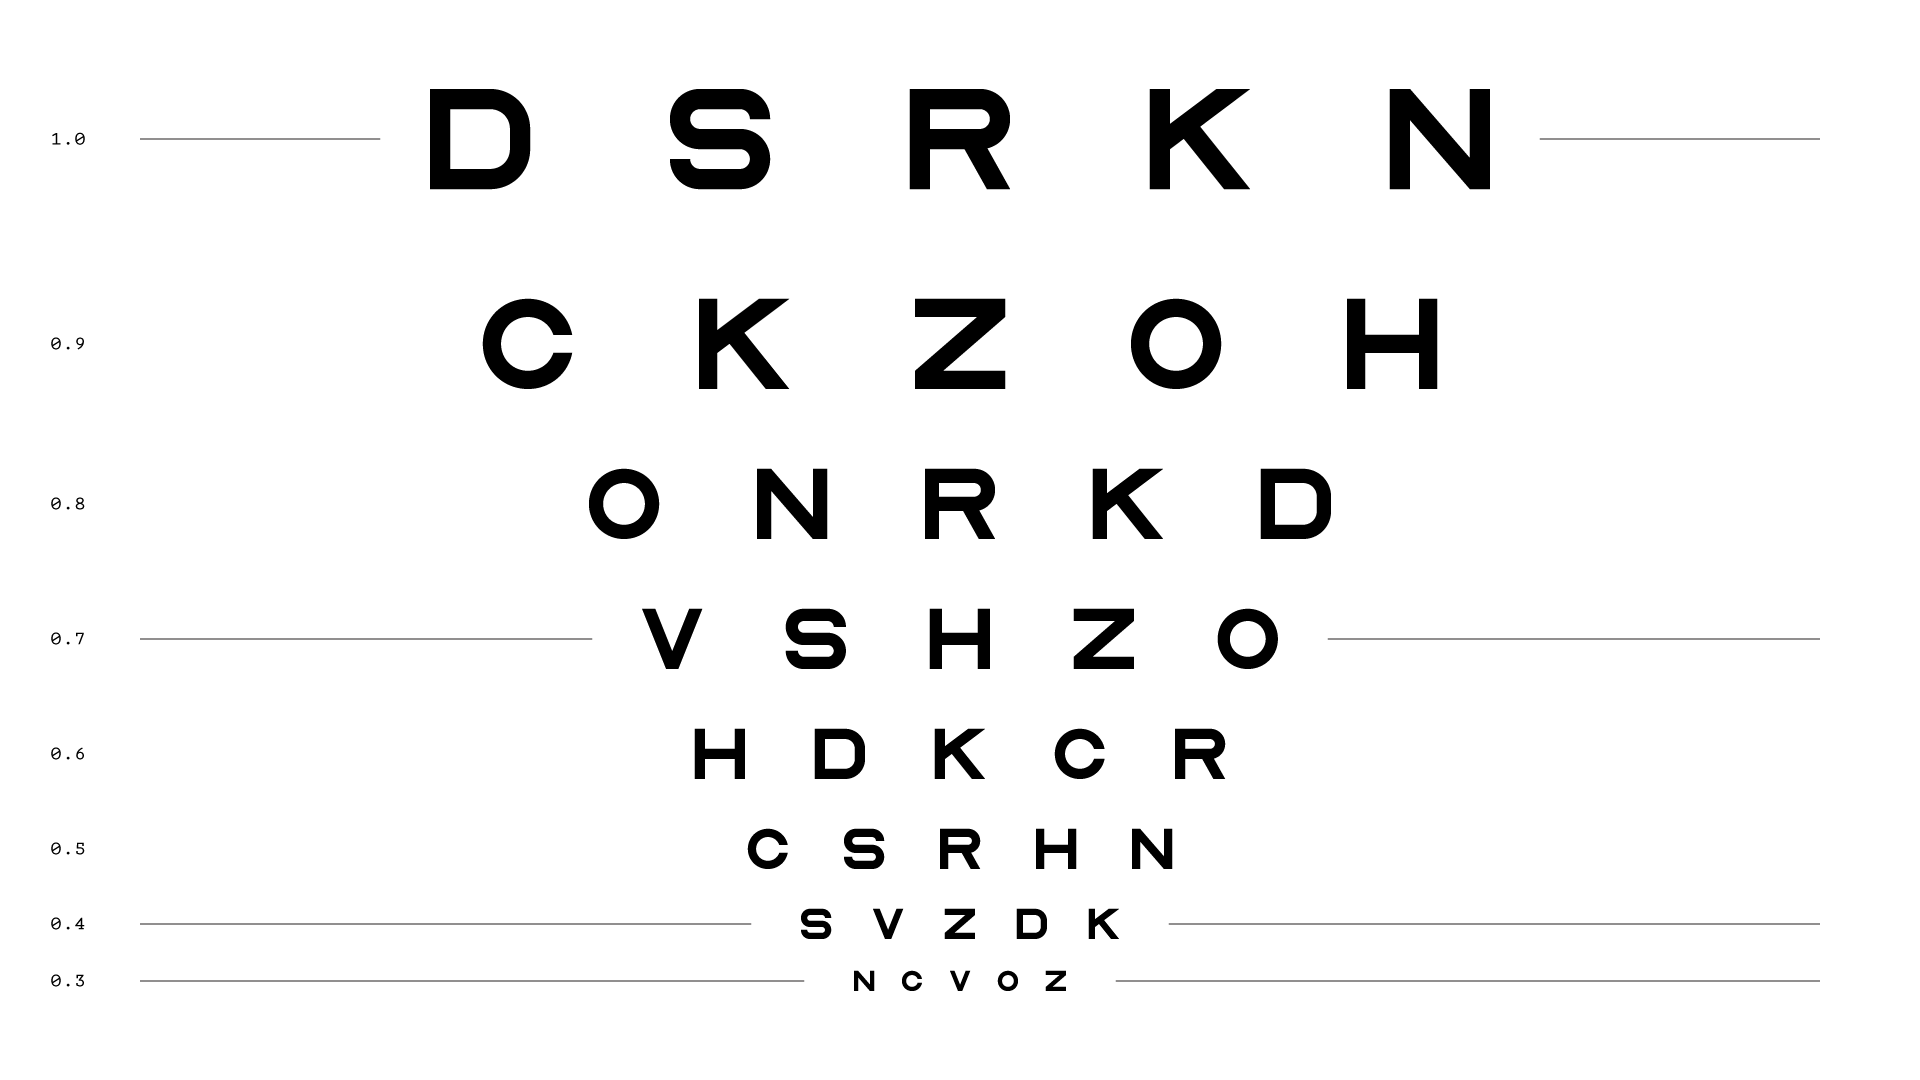
For a long time, looking at these at the optometrist and/or physician, I’d think something in the lines of oh, that’s horrible!, considering them poorly designed. This was, of course, a conclusion out of my own ignorance – but they still look ugly, though.
2.2 Visual Acuity, Not Legibility
In the midst of all these articles and interviews, I stumped into a widespread idea that was somewhat surprising to me – that optotypes are more legible. They’re not.
In fact, if optotypes were constructed to be highly legible, it would defeat its purpose: these are built to measure visual acuity, i.e., to test how capable your eyes are to distinguish between small details. As you can deduce, ambiguity is somewhat key and, as I stated before, ambiguity isn’t really legibility’s best friend.
But how is accuity measured? Why these charts?
Erik van Blokland has explained this way better than I could, but I’ll still try to summarize it:
If you have noticed at the optometrist, you look at the chart from a specific distance. And each optotype size corresponds to a different angle from your eyes’ lenses.
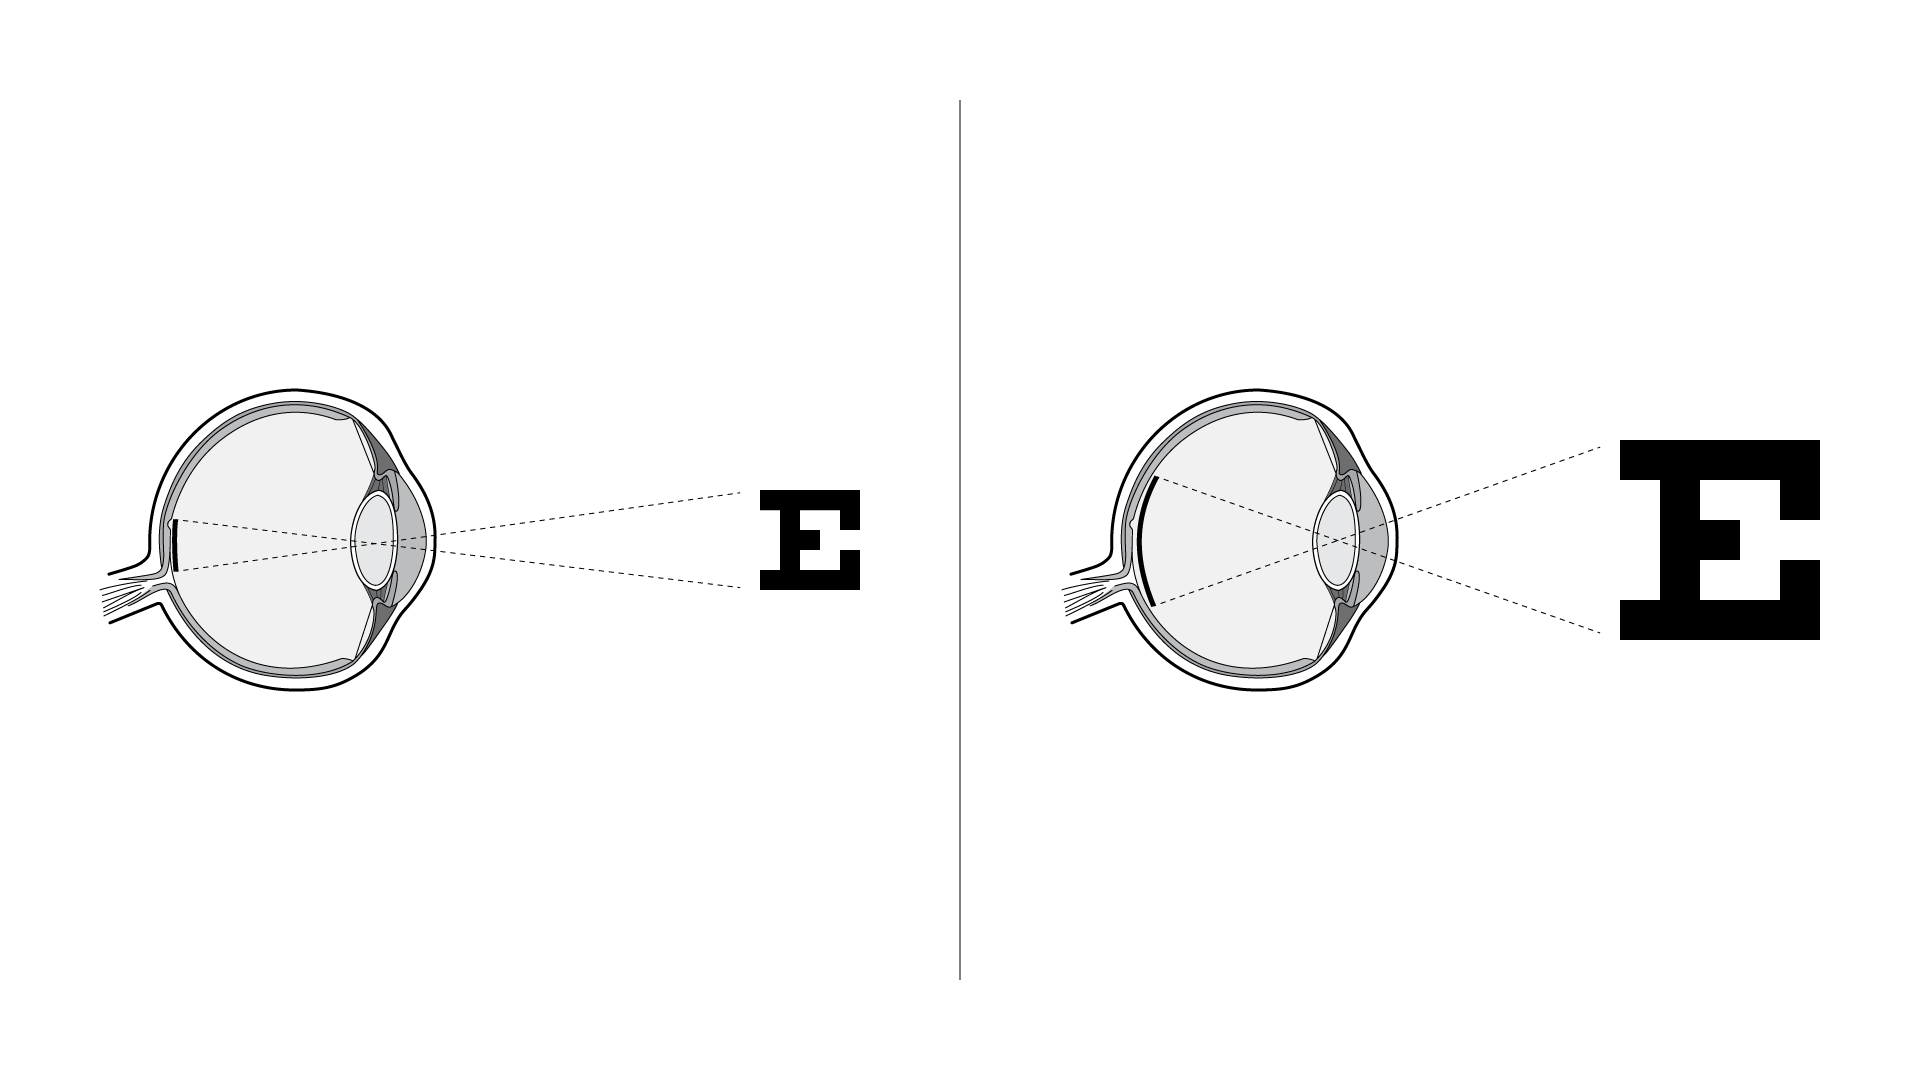
If that image projects itself onto your retina at different angles, the smaller the angle, the less photoreceptors are being used to see that figure.
For example, the 20/20 line corresponds to 5 arcminutes and we then know that around 10 photoreceptor cells are being used (in the fovea, where the highest concentration of cones is).
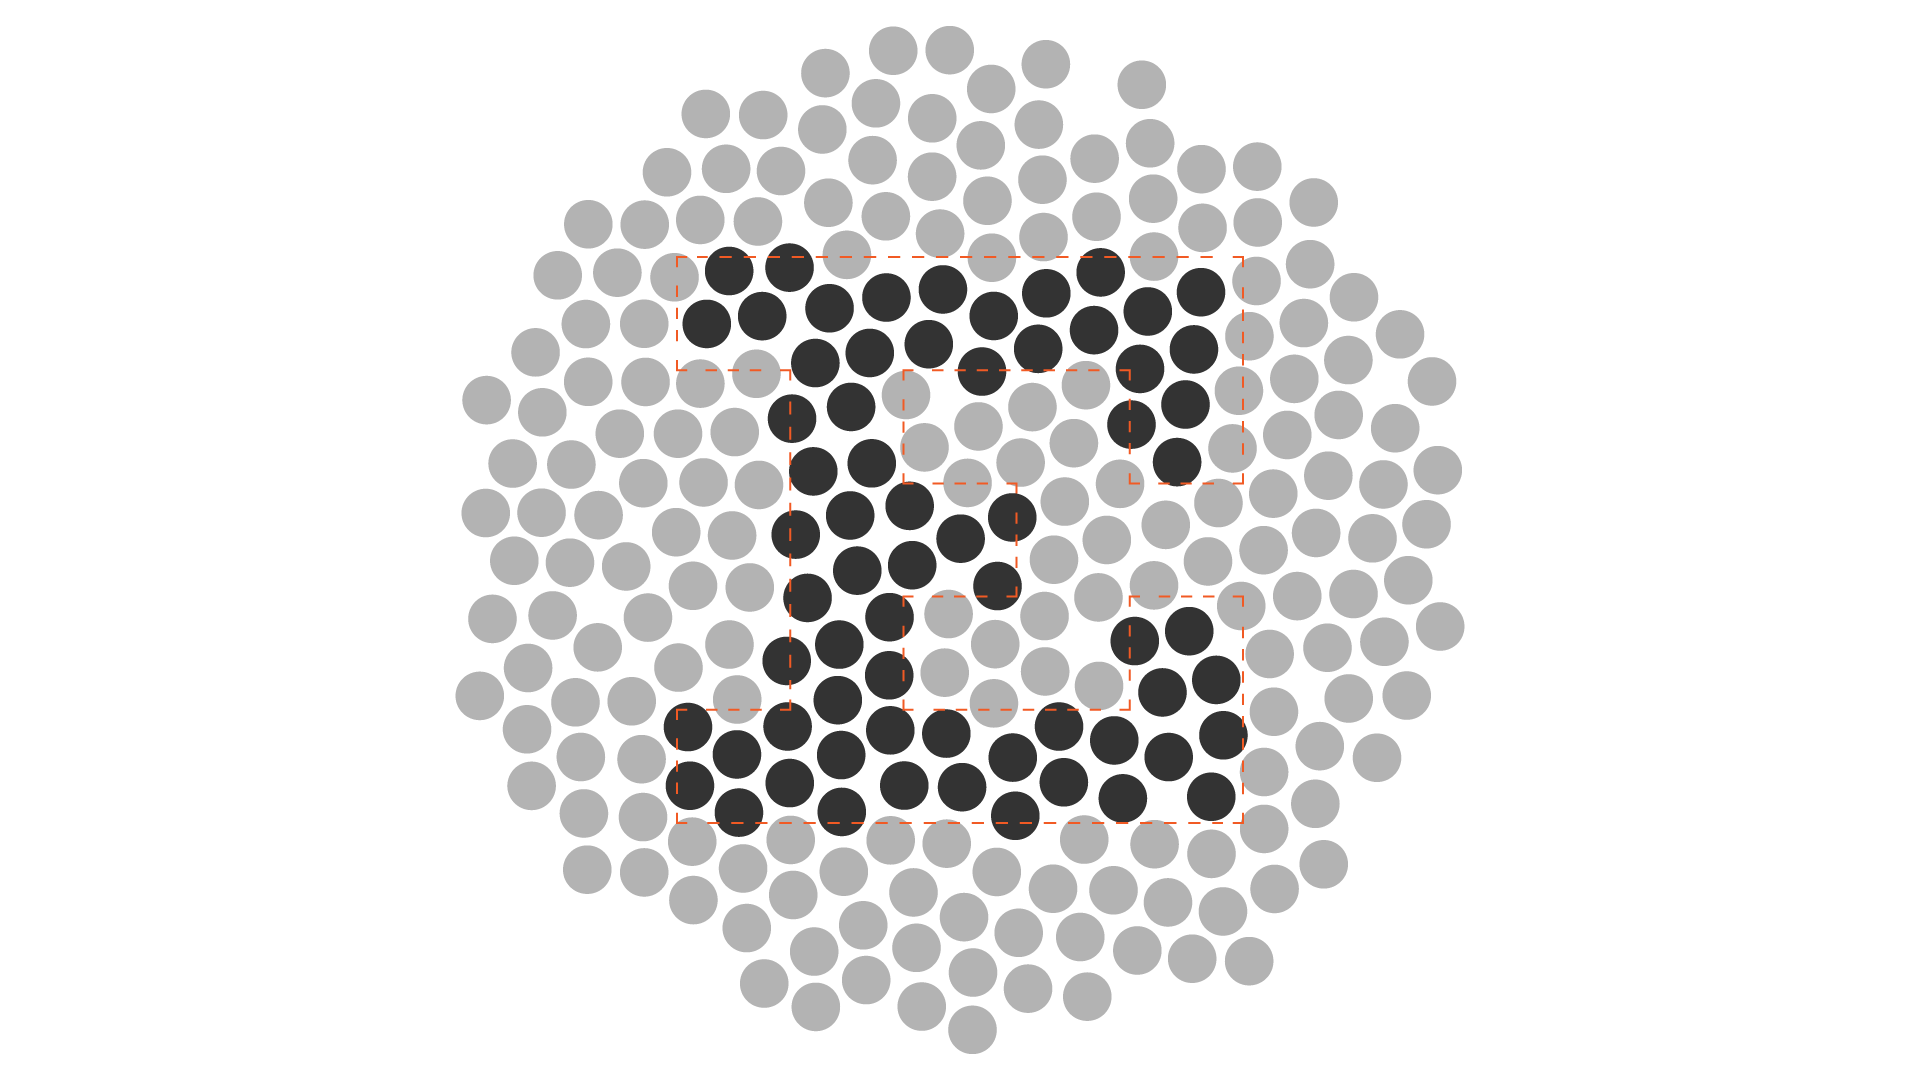
That is why optotypes (at least Schellen and Sloan) are designed in a 5×5 grid – each stroke corresponds roughly to 2 cells at 20/20.
3. Making Optician Sans
3.1 The Commission
As stated in §1, ANTI Hamar hired me to produce a bespoke typeface for one of their clients. The client is Optiker-K, a family-held Norwegian small business, providing optician and optometrist services since 1877.
So, for Optiker-K’s rebranding, Simen designed a first draft of the typeface, but something wasn’t quite right: at this stage, we stumbled upon eachother and he ended up hiring me.
3.2 The Brief
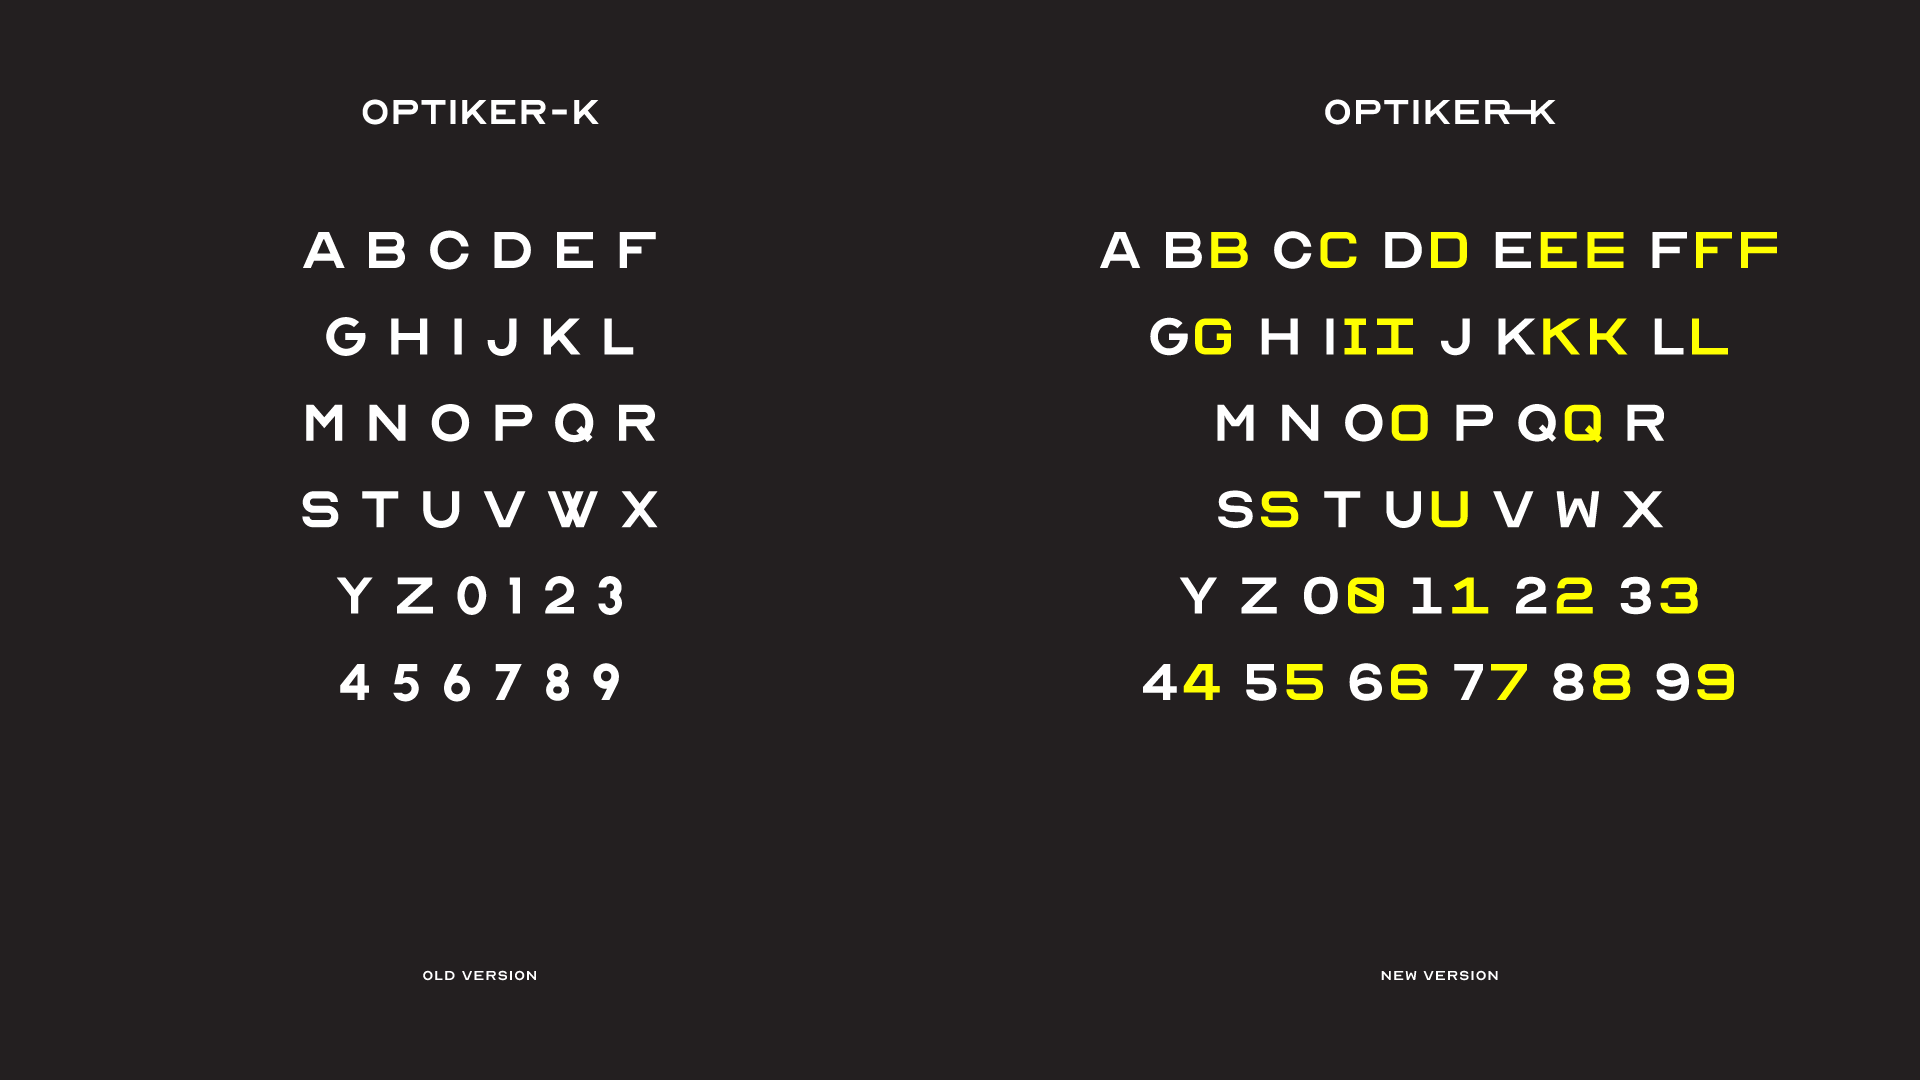
Initially, this was a calibration commission: to balance strokes, proportions, to correct node placements, to space it and hint it, to compile the typeface in a distribution-ready package.
In spite of this, what I got from the conversation with Simen was some sort of hey, can you make this work? proposal, so I started to look for inconsistencies – and ending up detouring from the brief.
You see, the Sloan letters weren’t built to work as a typeface: if you compare, say, the S with the C or the O, they seem stylistically unrelated. At some point, it struck me that we were dealing with glyphs from two different typefaces, almost randomly picked and joined together.
But our goal was to have a consistent look for the brand. Secretly (read: without asking), I redrew from scratch what Simen provided (in FontLab VI, as usual, since you’ve been asking), in two character sets: a more rounded, friendlier one (inspired by the O and C shapes); and a more blocky one (looking at the S).
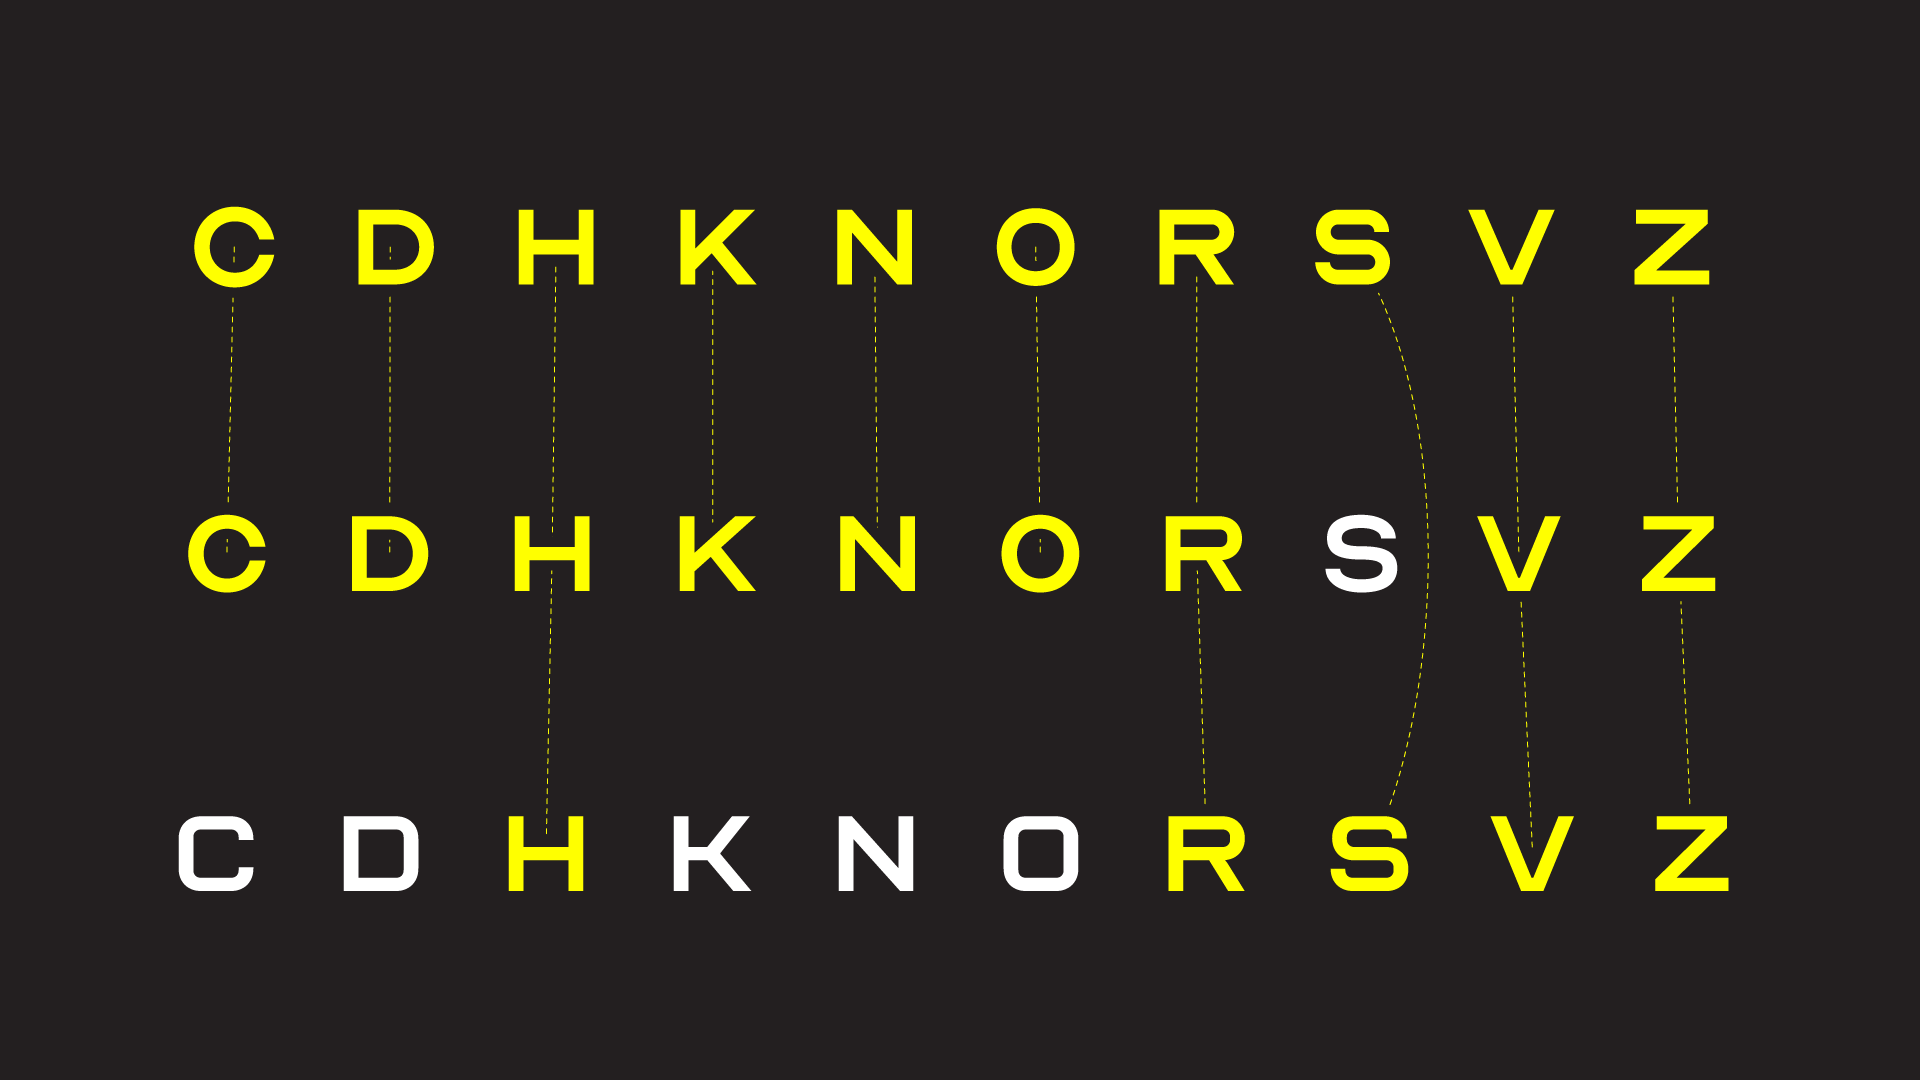
Then, with a hint of fear, I pitched them to Simen, who cheerfully agreed straight away. *phew*
3.3 Logo-in-a-font
Apart from the two alternate character sets, Optician Sans offers an Easter Egg: while looking for a fast way to deploy Optiker-K’s logotype, we decided to include it inside the font itself; so whenever you type O-K or Optiker-K, the logotype automagically appears!
4. Hello Internet!
Free. Yes, for free.
The client, Optiker-K, decided to release the typeface for free. So you can send e-mails to them and to ANTI Hamar, filled with heart emoticons and unicorn hugs.
Upon release, well, the web went crazy, way beyond what we expected, especially for a font made to work in English and Norwegian only.
So thanks for the love, everyone! It feels really good to have made something that everyone is enjoying so much!
4.1 The Future – Present, actually.
With all this attention and cheering crowd, we decided to take some small steps forward:
- The typeface is available on GitHub – if you want to keep track and fork it to your own servings, please do!
- The License changed to SIL OFL to make this possible;
- We’re slowly expanding the font to support more languages!
5. Wrapping Up
I hope enjoyed knowing a bit more about this typeface. If you wish to know a bit more on ANTI’s side, check Simen’s article on Medium.
And, if you haven’t already, subscribe below to keep in touch! Cheers!
References and Further Reading:
- Optician Sans microsite;
- Completing the work of a typeface that was started decades ago, Simen Schikulski;
- Testing The Limits of Human Vision, Verge Science;
- Optics, Erik van Blokland;
- Visual Acuity, Wikipedia;
Making a Font: Maximal – Part III
Welcome back to this series about the production of Maximal. If you’re a newcomer, don’t forget to check Part I and Part II, so you know where you’re at; or better, what we’re talking about here.
This article is about programming. Since we’re dealing with such a massive amount of glyphs, developing/adapting some tools to make production easier is a big deal. Besides, the (pseudo-[we’ll get to that]) randomness of this typeface involves – you got it – programming.
1. Generating Glyphs
Let’s start with something not so code-y.
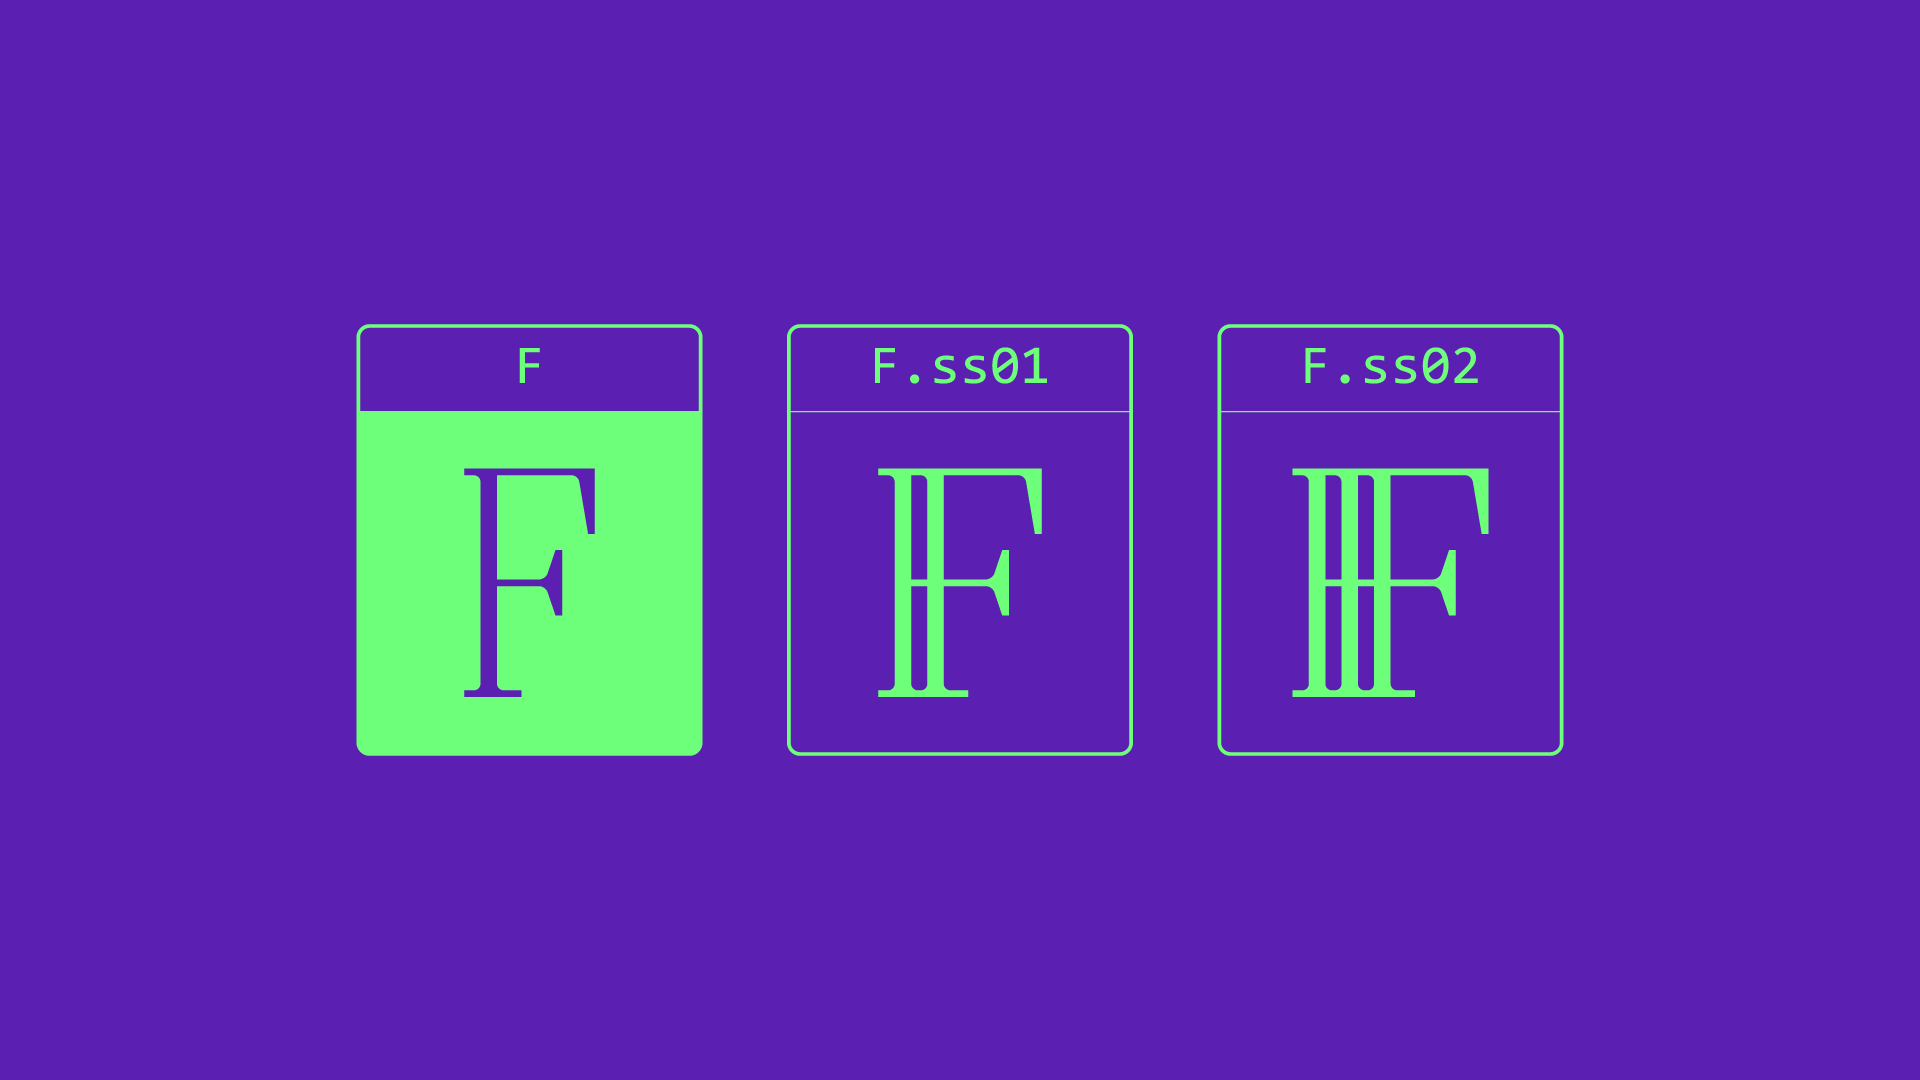
As planned, we need 30 glyphs per letter, apart from the main glyph. For organization and management sake, if the base glyph is E, for example, I want to call the variations E.ss01, E.ss02, E.ss03 and so on.
Why? Well, I use FontLab Studio, and it lets me batch generate glyphs. At the same time, it ignores what’s after the period and generates a component with the letter E, which is handy to start editing. So, in FontLab Studio, if I want to generate a whole bunch of glyphs, I need to input something like this:
E.ss01 E.ss02 E.ss03 E.ss04 ...
Writing down 30 of these, one by one, for hundreds of glyphs, is tiresome. So, I’ve made this little app, just for this project, that does just that. Feel free to use it for your own needs, since I’ve thought that you might just do that and made it in a way that you can choose your own prefixes.
I won’t go over the app’s programming, though, since it’s plain old HTML + Javascript (something very easy to find on Google for clarification) and you can check the source code on the spot.
2. Making Classes
Most of OpenType features work by substitution glyphs and/or groups of glyphs. For example, if you have a f+i ligature – and let’s say that that ligature has the name f_i – your code to display the ligature whenever you type fi would look like this:
sub f i by f_i;
Simple, right?
Now, as we’ve settled on Part II, we have 30 variations of each glyph, which leaves us with a bit more than 13.000 glyphs to manage. Can you imagine coding everything glyph by glyph? Not a very appealing idea, right?
Well, we have classes at our disposal. Basically, we can grab a bunch of glyphs and store them in a class, repeat that for every style set (while keeping the same order) and instead of substituting the glyphs, we substitute the class. For those staring and blinking: instead of coding 13.000 times, we’ll just make it 31. Bear with me.
In OpenType coding, a class is identified by the prefix @. So, let’s say we have two classes, class1 and class2. If we want to substitute all the glyphs stored in class1 by the glyphs in class2, it would something like this:
sub @class1 by @class2;
If it’s your first time tinkering with OpenType features (or not, anyway), have a look at Tal Leming‘s The OpenType Cookbook and bookmark it. Seriously: it’s that awesome (and did I mention free?).
2.1 So, What’s What?
So now that we know how classes work and the basics for writing OpenType substitution routines, lets go through the classes in our font. Here’s how I’m naming them:
ss00 => Our default glyphs
ss01 => Stylistic Set 01
ss02 => Stylistic Set 02
...
And so on. My main goal here is to draw your attention to ss00, which is our non-modified glyph set. This class will be the default one and no glyph substitution will be applied.
The reason for this is, well, people might want to use it without the pseudo-random craziness, as well as any other style. At the same time, you might want to change a glyph or two, without the program changing it back to some other glyph.
With this said, we have three features in our OpenType code:
- Default: how the font behave out-of-the-box;
- Stylistic Sets: the 30 different glyph sets;
- Contextual Alternates: where the pseudo-random magic happens, with glitter and fairies.
I won’t dwell into the first two, since they are very simple and a lot of people around the interwebs have already documented it way better than I could. Again, I recommend Tal Leming’s OT Cookbook.
3. OpenType Random?
OpenType does have a rand feature, introduced by Adobe (S3), but it remains largely unsupported (yes, even by Adobe). XeTeX seems to support it, though, since it allows raw OpenType features.
The usual way type designers go around this, is by creating a pseudo-random glyph substitution routine that cycles throughout.
3.1 True Random vs. Pseudo-Random
So, why isn’t rand widely implemented? Adam Twardoch, in this Fontlab Forum thread, has some very insightful points:
- Each time you open a document (or every time it refreshes the viewport), the rand feature alters your text completely;
- If the alternate glyphs have different widths and/or metrics, the text length also changes (day 1 – 20 pages, day 2 – 19 pages);
- Manual adjustments, such as letter-spacing or line breaks, would have to be done every single time you open a document;
So, pseudo-random code, instead of pure randomness, grants control, it’s predictable and avoids headaches in processing power and editing. Sure, there might be situations where a full-throttle random implementation is desired but, hey – you can always code your own to tailor-suit your needs.
3.2 Pseudo-random Substitution
Pieter van Rosmalen, in this thread on Typophile, shares the code that will be our basis for this font. Here’s the code that we’ll be using as a starting point:
feature salt {
   lookup rotate {
      sub @ss00 @ss00' by @ss01;
      sub @ss01 @ss00' by @ss02;
      sub @ss02 @ss00' by @ss03;
      sub @ss03 @ss00' by @ss04;
      sub @ss04 @ss00' by @ss05;
   } rotate;
   lookup rotate;
} salt;
There are only 5 classes, instead of 30, because I want you to understand this: making this work with 30 or more (and we’ll get there), is simply a matter of extending this logic.
So, first of all, pay attention to the single-quote mark. In OpenType, this means change just this one. Let’s imagine this scenario: we want that everytime that we type EE, we want the last E to be substituted by the glyph E.ss01. The code would look something like this:
sub E E' by E.ss01;
Simple, right? Let’s move on.
3.3 Extending the Code
I did mention that our final code would be an extension of this. So, we want the following to happen and in this order:
- Check the first pair and change the last glyph with another one;
- Store the last glyph of the first pair and use it as the first of the second pair;
- Change the last glyph of the second pair;
- Do this throughout the algorithm.
This doesn’t seem random at all, right? Well, the trick here is to appear random: so if we have an algorithm that is complex and big enough, it will appear random.
So how will we make this algorithm easily? Automation, again, for the win: I wrote another HTML/Javascript program just to do this task. You can find it here.
And again, the source code is viewable, so use it however you want to.
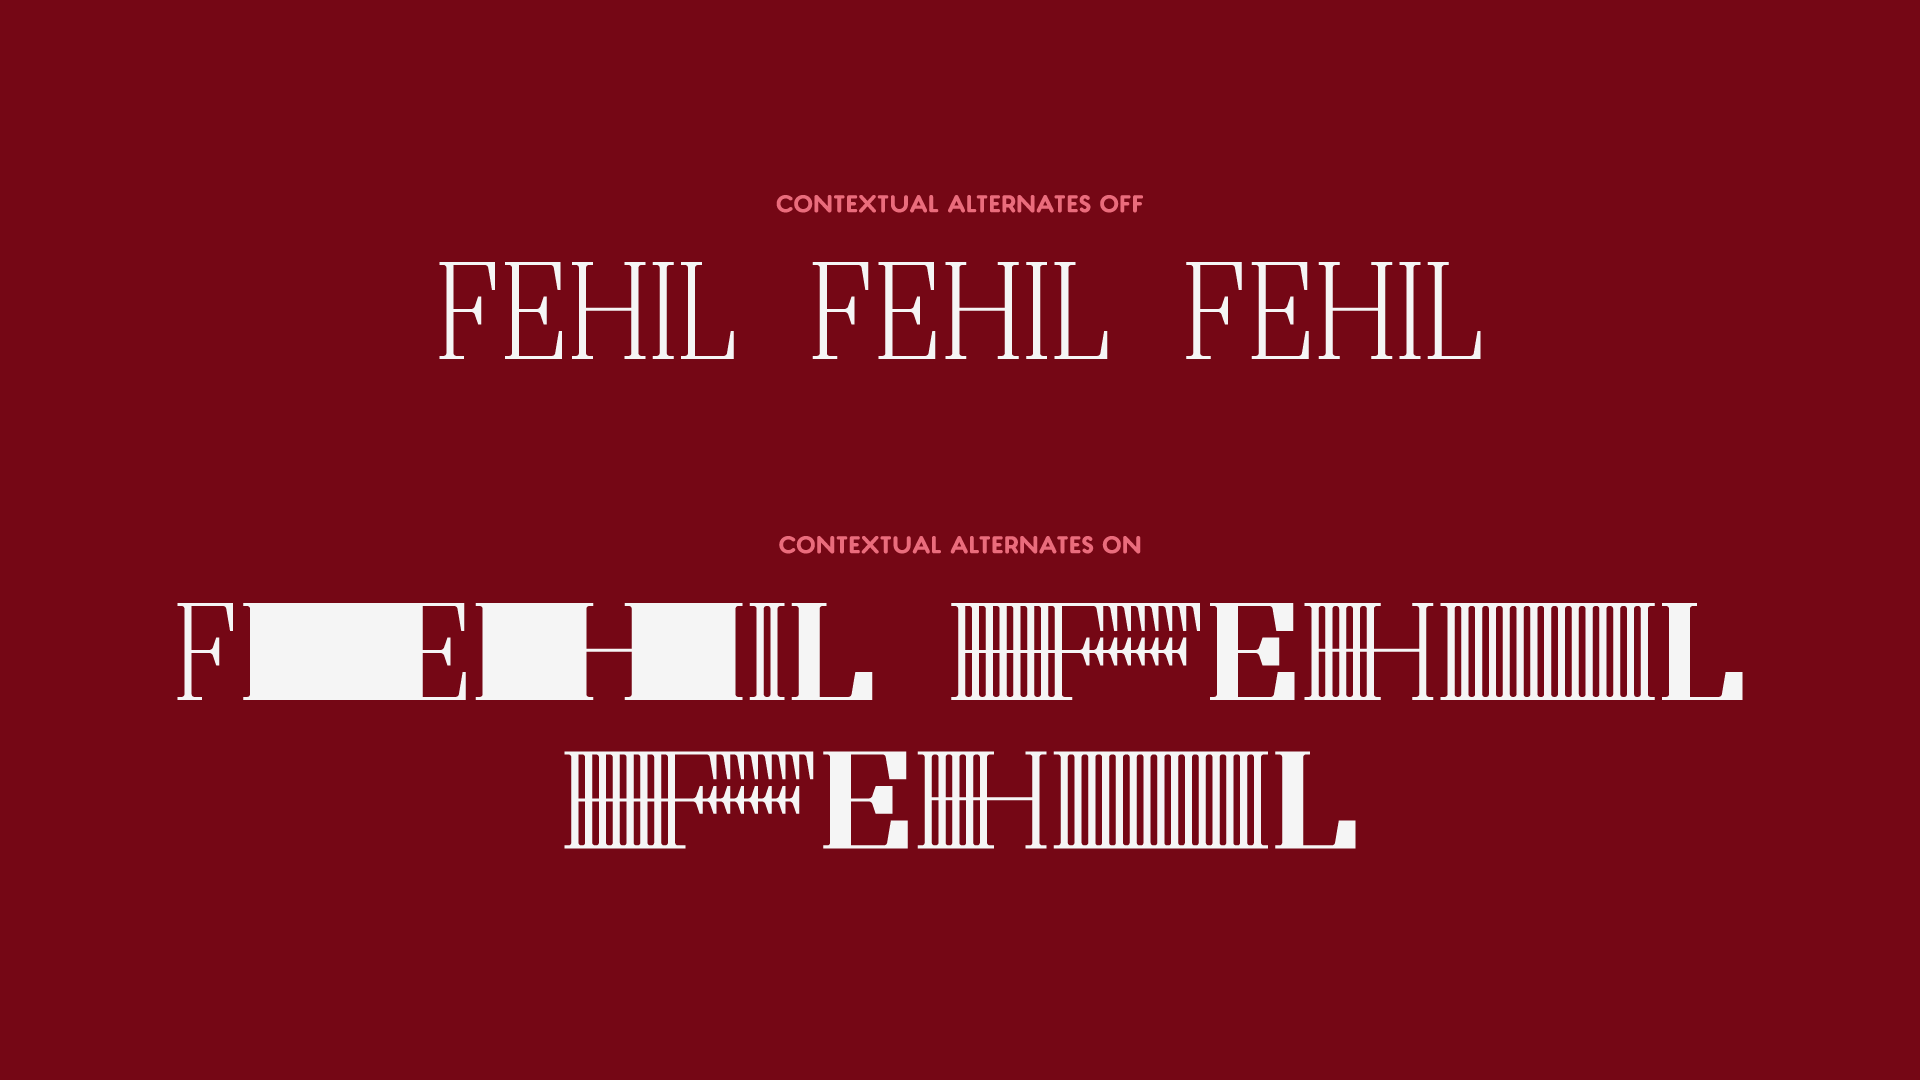
So now, when we type something in, our font looks like this:
4. Wrapping Up
I hope you enjoyed this post! If you did, you can always share by using the buttons below. For more juice, scroll down and subscribe to the mailing list!
See you in Part IV! Cheers!