Making a Font: Maximal – Part III
Welcome back to this series about the production of Maximal. If you’re a newcomer, don’t forget to check Part I and Part II, so you know where you’re at; or better, what we’re talking about here.
This article is about programming. Since we’re dealing with such a massive amount of glyphs, developing/adapting some tools to make production easier is a big deal. Besides, the (pseudo-[we’ll get to that]) randomness of this typeface involves – you got it – programming.
1. Generating Glyphs
Let’s start with something not so code-y.
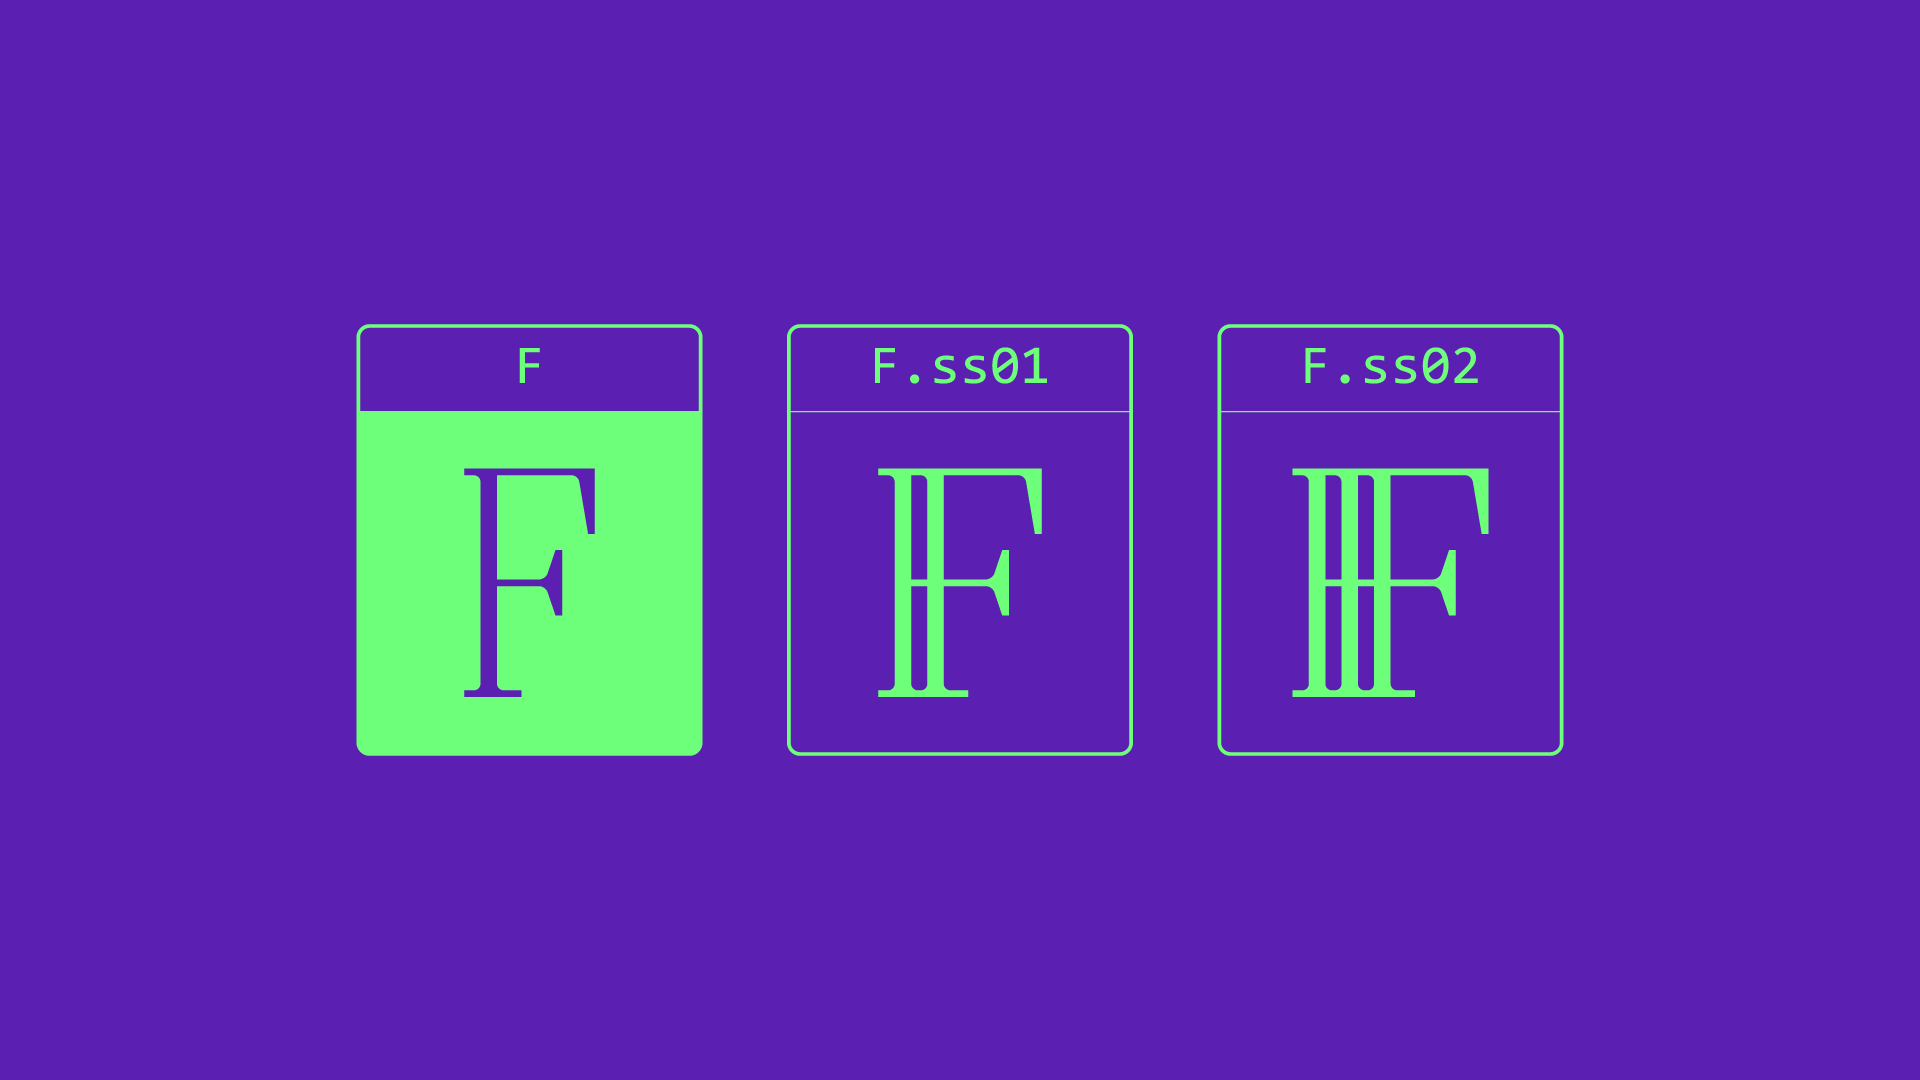
As planned, we need 30 glyphs per letter, apart from the main glyph. For organization and management sake, if the base glyph is E, for example, I want to call the variations E.ss01, E.ss02, E.ss03 and so on.
Why? Well, I use FontLab Studio, and it lets me batch generate glyphs. At the same time, it ignores what’s after the period and generates a component with the letter E, which is handy to start editing. So, in FontLab Studio, if I want to generate a whole bunch of glyphs, I need to input something like this:
E.ss01 E.ss02 E.ss03 E.ss04 ...
Writing down 30 of these, one by one, for hundreds of glyphs, is tiresome. So, I’ve made this little app, just for this project, that does just that. Feel free to use it for your own needs, since I’ve thought that you might just do that and made it in a way that you can choose your own prefixes.
I won’t go over the app’s programming, though, since it’s plain old HTML + Javascript (something very easy to find on Google for clarification) and you can check the source code on the spot.
2. Making Classes
Most of OpenType features work by substitution glyphs and/or groups of glyphs. For example, if you have a f+i ligature – and let’s say that that ligature has the name f_i – your code to display the ligature whenever you type fi would look like this:
sub f i by f_i;
Simple, right?
Now, as we’ve settled on Part II, we have 30 variations of each glyph, which leaves us with a bit more than 13.000 glyphs to manage. Can you imagine coding everything glyph by glyph? Not a very appealing idea, right?
Well, we have classes at our disposal. Basically, we can grab a bunch of glyphs and store them in a class, repeat that for every style set (while keeping the same order) and instead of substituting the glyphs, we substitute the class. For those staring and blinking: instead of coding 13.000 times, we’ll just make it 31. Bear with me.
In OpenType coding, a class is identified by the prefix @. So, let’s say we have two classes, class1 and class2. If we want to substitute all the glyphs stored in class1 by the glyphs in class2, it would something like this:
sub @class1 by @class2;
If it’s your first time tinkering with OpenType features (or not, anyway), have a look at Tal Leming‘s The OpenType Cookbook and bookmark it. Seriously: it’s that awesome (and did I mention free?).
2.1 So, What’s What?
So now that we know how classes work and the basics for writing OpenType substitution routines, lets go through the classes in our font. Here’s how I’m naming them:
ss00 => Our default glyphs
ss01 => Stylistic Set 01
ss02 => Stylistic Set 02
...
And so on. My main goal here is to draw your attention to ss00, which is our non-modified glyph set. This class will be the default one and no glyph substitution will be applied.
The reason for this is, well, people might want to use it without the pseudo-random craziness, as well as any other style. At the same time, you might want to change a glyph or two, without the program changing it back to some other glyph.
With this said, we have three features in our OpenType code:
- Default: how the font behave out-of-the-box;
- Stylistic Sets: the 30 different glyph sets;
- Contextual Alternates: where the pseudo-random magic happens, with glitter and fairies.
I won’t dwell into the first two, since they are very simple and a lot of people around the interwebs have already documented it way better than I could. Again, I recommend Tal Leming’s OT Cookbook.
3. OpenType Random?
OpenType does have a rand feature, introduced by Adobe (S3), but it remains largely unsupported (yes, even by Adobe). XeTeX seems to support it, though, since it allows raw OpenType features.
The usual way type designers go around this, is by creating a pseudo-random glyph substitution routine that cycles throughout.
3.1 True Random vs. Pseudo-Random
So, why isn’t rand widely implemented? Adam Twardoch, in this Fontlab Forum thread, has some very insightful points:
- Each time you open a document (or every time it refreshes the viewport), the rand feature alters your text completely;
- If the alternate glyphs have different widths and/or metrics, the text length also changes (day 1 – 20 pages, day 2 – 19 pages);
- Manual adjustments, such as letter-spacing or line breaks, would have to be done every single time you open a document;
So, pseudo-random code, instead of pure randomness, grants control, it’s predictable and avoids headaches in processing power and editing. Sure, there might be situations where a full-throttle random implementation is desired but, hey – you can always code your own to tailor-suit your needs.
3.2 Pseudo-random Substitution
Pieter van Rosmalen, in this thread on Typophile, shares the code that will be our basis for this font. Here’s the code that we’ll be using as a starting point:
feature salt {
   lookup rotate {
      sub @ss00 @ss00' by @ss01;
      sub @ss01 @ss00' by @ss02;
      sub @ss02 @ss00' by @ss03;
      sub @ss03 @ss00' by @ss04;
      sub @ss04 @ss00' by @ss05;
   } rotate;
   lookup rotate;
} salt;
There are only 5 classes, instead of 30, because I want you to understand this: making this work with 30 or more (and we’ll get there), is simply a matter of extending this logic.
So, first of all, pay attention to the single-quote mark. In OpenType, this means change just this one. Let’s imagine this scenario: we want that everytime that we type EE, we want the last E to be substituted by the glyph E.ss01. The code would look something like this:
sub E E' by E.ss01;
Simple, right? Let’s move on.
3.3 Extending the Code
I did mention that our final code would be an extension of this. So, we want the following to happen and in this order:
- Check the first pair and change the last glyph with another one;
- Store the last glyph of the first pair and use it as the first of the second pair;
- Change the last glyph of the second pair;
- Do this throughout the algorithm.
This doesn’t seem random at all, right? Well, the trick here is to appear random: so if we have an algorithm that is complex and big enough, it will appear random.
So how will we make this algorithm easily? Automation, again, for the win: I wrote another HTML/Javascript program just to do this task. You can find it here.
And again, the source code is viewable, so use it however you want to.
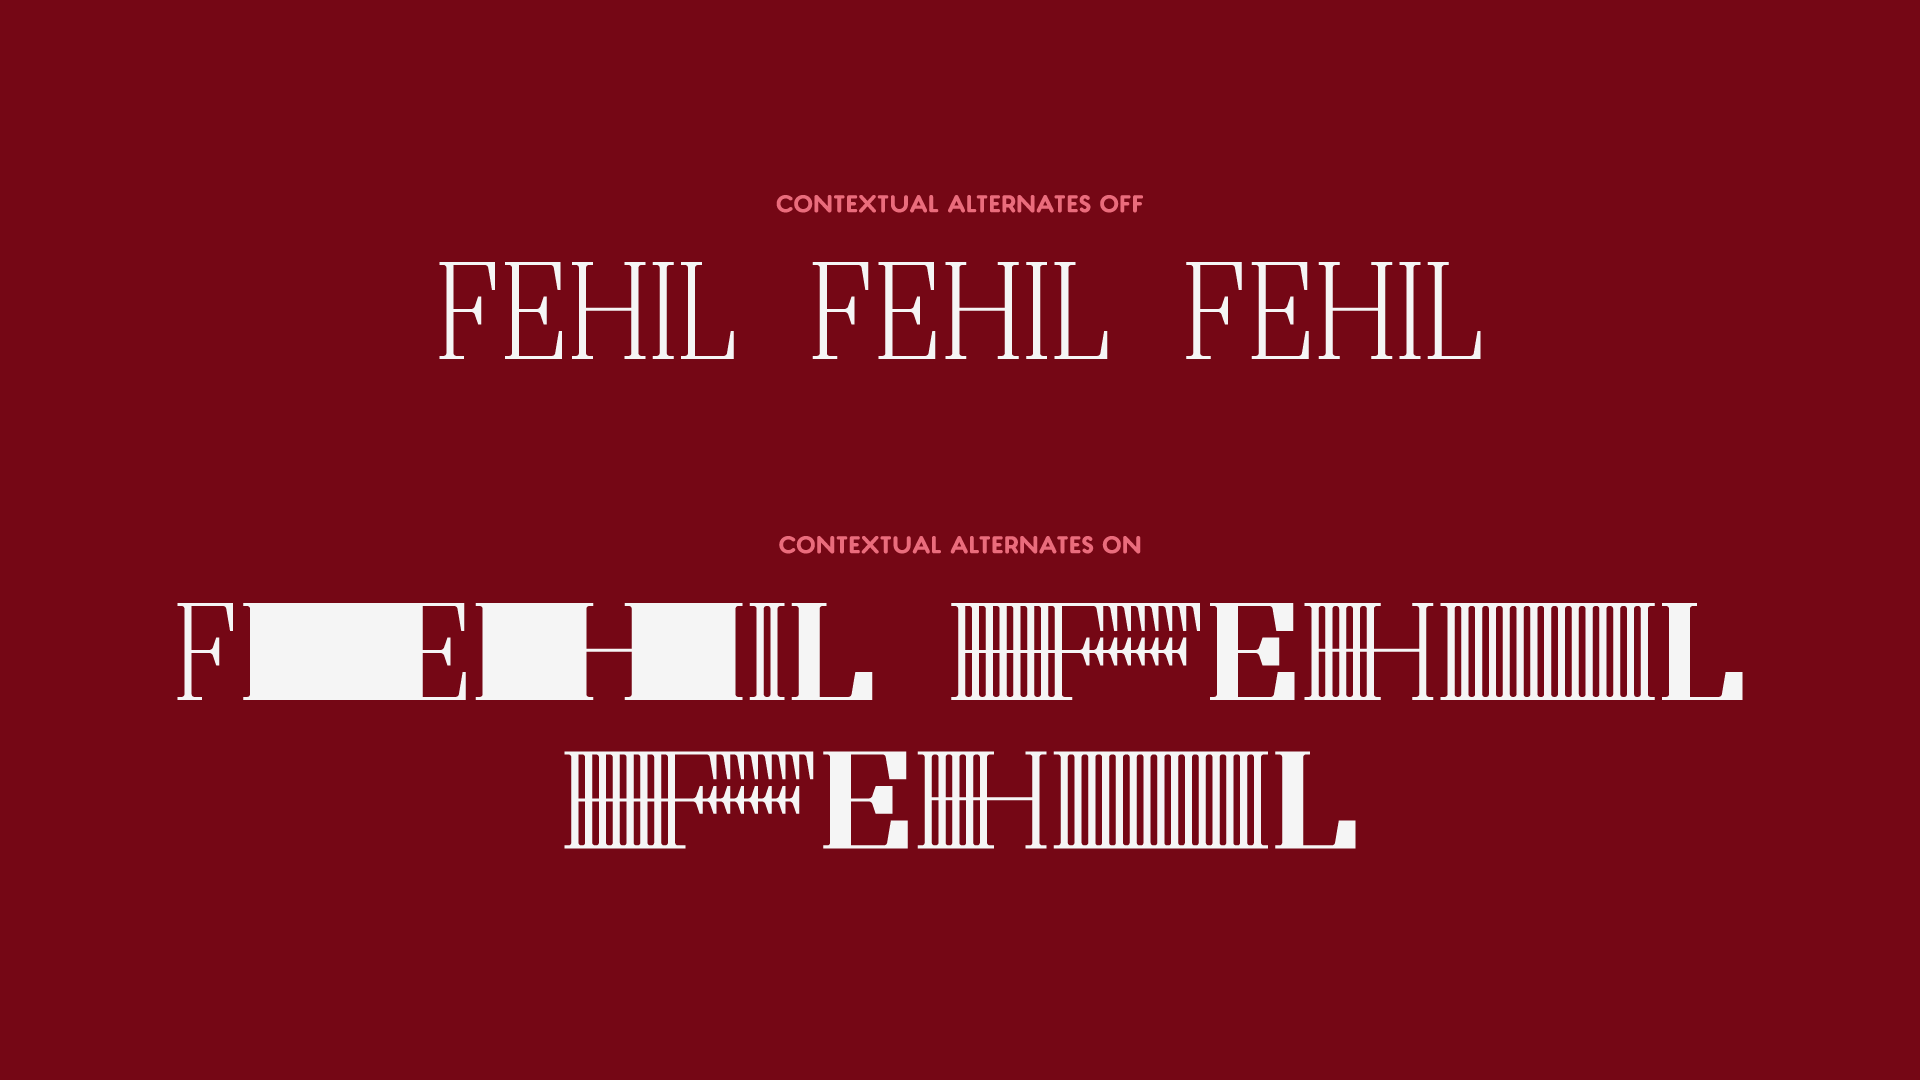
So now, when we type something in, our font looks like this:
4. Wrapping Up
I hope you enjoyed this post! If you did, you can always share by using the buttons below. For more juice, scroll down and subscribe to the mailing list!
See you in Part IV! Cheers!
References:
Making a Font: Maximal – Part II
I hope you guys had a great Easter (if you’re culturally inclined for such practice – if not, I hope you had a great week).
So, here we are, back on track. In the previous post, we talked about some preparatory steps regarding the conceptualization of the font in hand. Today, we’re going to start analysing an initial prototype, so we can make some early choice of the development to come.
But before we dive into it, I want to thank you guys for such an overwhelming response to the first post. I was really shy to promote it, since I thought it was a very initial approach to this subject, and I thought it was best to leave a more intense promotion to later on, when there was more reading material.
I’m humbled that you guys found a preparatory post interesting enough to share it so much, so my deepest thank you for your attention! I owe my motivation to you and your kindness, so I have nothing to do but my best! Thank you all!
So, to avoid more sappiness from my behalf, let’s get to the point.
1. How many styles?
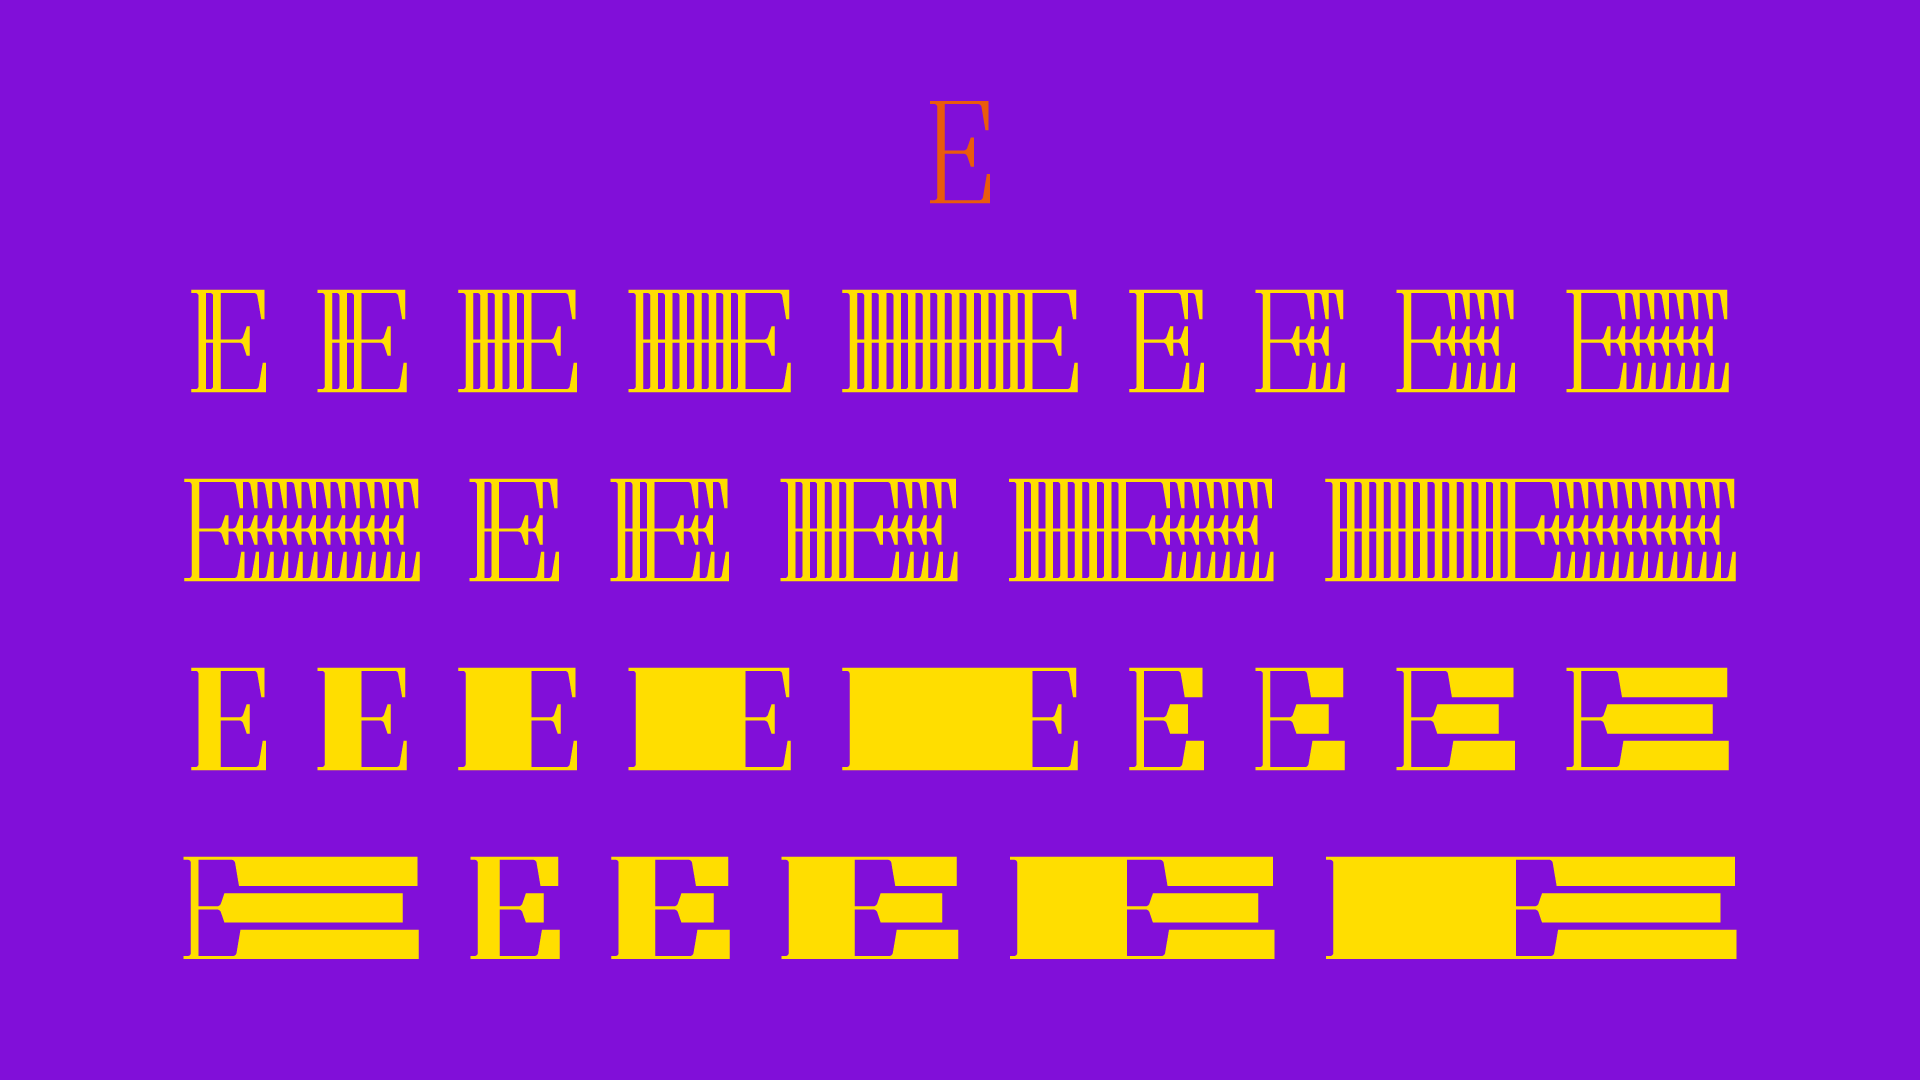
At this point, this is the most crucial decision to make. As we are going to see in §4, this factor determines how lengthy this process will be.
The only reason why I should be concerned with the time this will take to make is that I want to keep you interested. Since most of you guys are casual visitors (meaning not subscribers [but you can subscribe at the bottom of this page]), this attention can easily go into the void.
To avoid that, I have to consider time. Or you can simply scroll down and subscribe to the newsletter.
Let’s say that we don’t have to worry about time. In this scenario, if we consider the “repetition” model (read about it in the previous post, §3 and §5), a linear incrementation would be the best one, right? Well, sort of.
Yes, it would give you more manual control, but the point here is about random substitution. And the glyph width variation should be extreme enough, since this is not about subtlety, but boldness.
Still, a natural or organic progression, although extreme, is welcome. So, here’s the solution: the Fibonacci sequence. The sequence goes like this:
1, 1, 2, 3, 5, 8, 13, 21, 34, …
The logic here is that any number is the addition of the previous two. In our case, we can skip the 1’s, since that’s our base glyph. And since we want 5 variations of expansion/repetition to each side (and both), we’ll use the numbers from 2 to 13.
So, we have 1 (our base glyph), 2, 3, 5, 8 and 13. The variations look something like this:
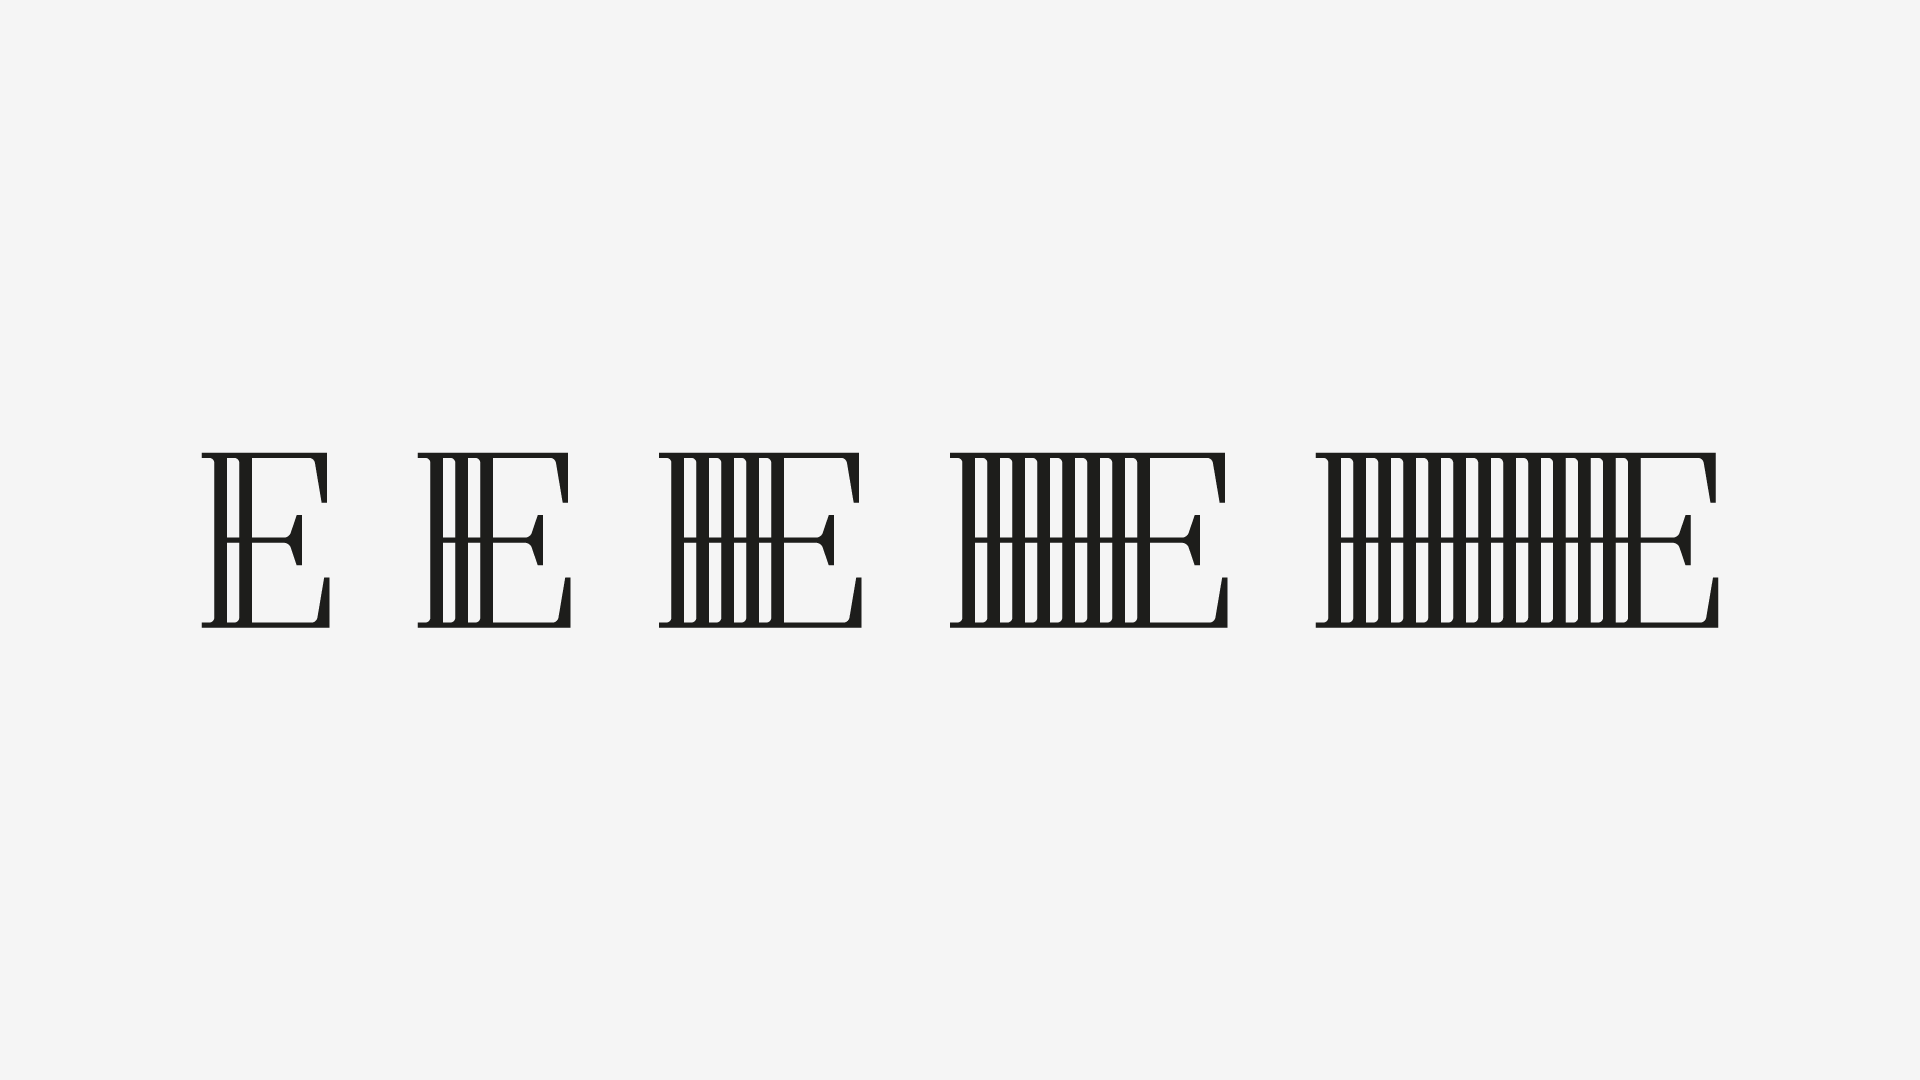
Then, as you saw in the image that opens this section, the same happens to the other side of the glyph and then to both sides. And then we make the “expanded” variations, using the repetition as the base. We’ll talk about that in a tick, in §3.
So, with 5 variations to each side, as well as 5 for both, in two sets (“expanded” and “repetition”) we have 30 stylistic sets, apart from the default glyph. That means 31 variation per letter. *heavy breathing*
2. The Base Glyphs
I have only two characters drawn, at this stage: E and F. And their 30 variations.
Now I’m more concerned with prototyping it, or better, to get the tech stuff sorted out before the drawing process; that’s why you’re seeing the same letters over and over again.
As this series go through, expect the tech geekness to decrease (although the next post or two will be about OpenType programming and maybe some Python macro stuff) and the drawing aspects to be mentioned more and more.
But as formal characteristics, the E can tell a lot, in our case. It can tell us quite nicely how the serifs will work, as well as how these elements work with the expansion/repetition. Of course, I’m still in the dark about the curved and diagonal shapes (although they’re playing cheerfully in my head, but that doesn’t mean it will play out properly once drawn).
I’m hoping to draw some very classic, rational and somewhat bland capitals. I want the magic to occur with the variations, not with the base forms.
3. Expanding Processes
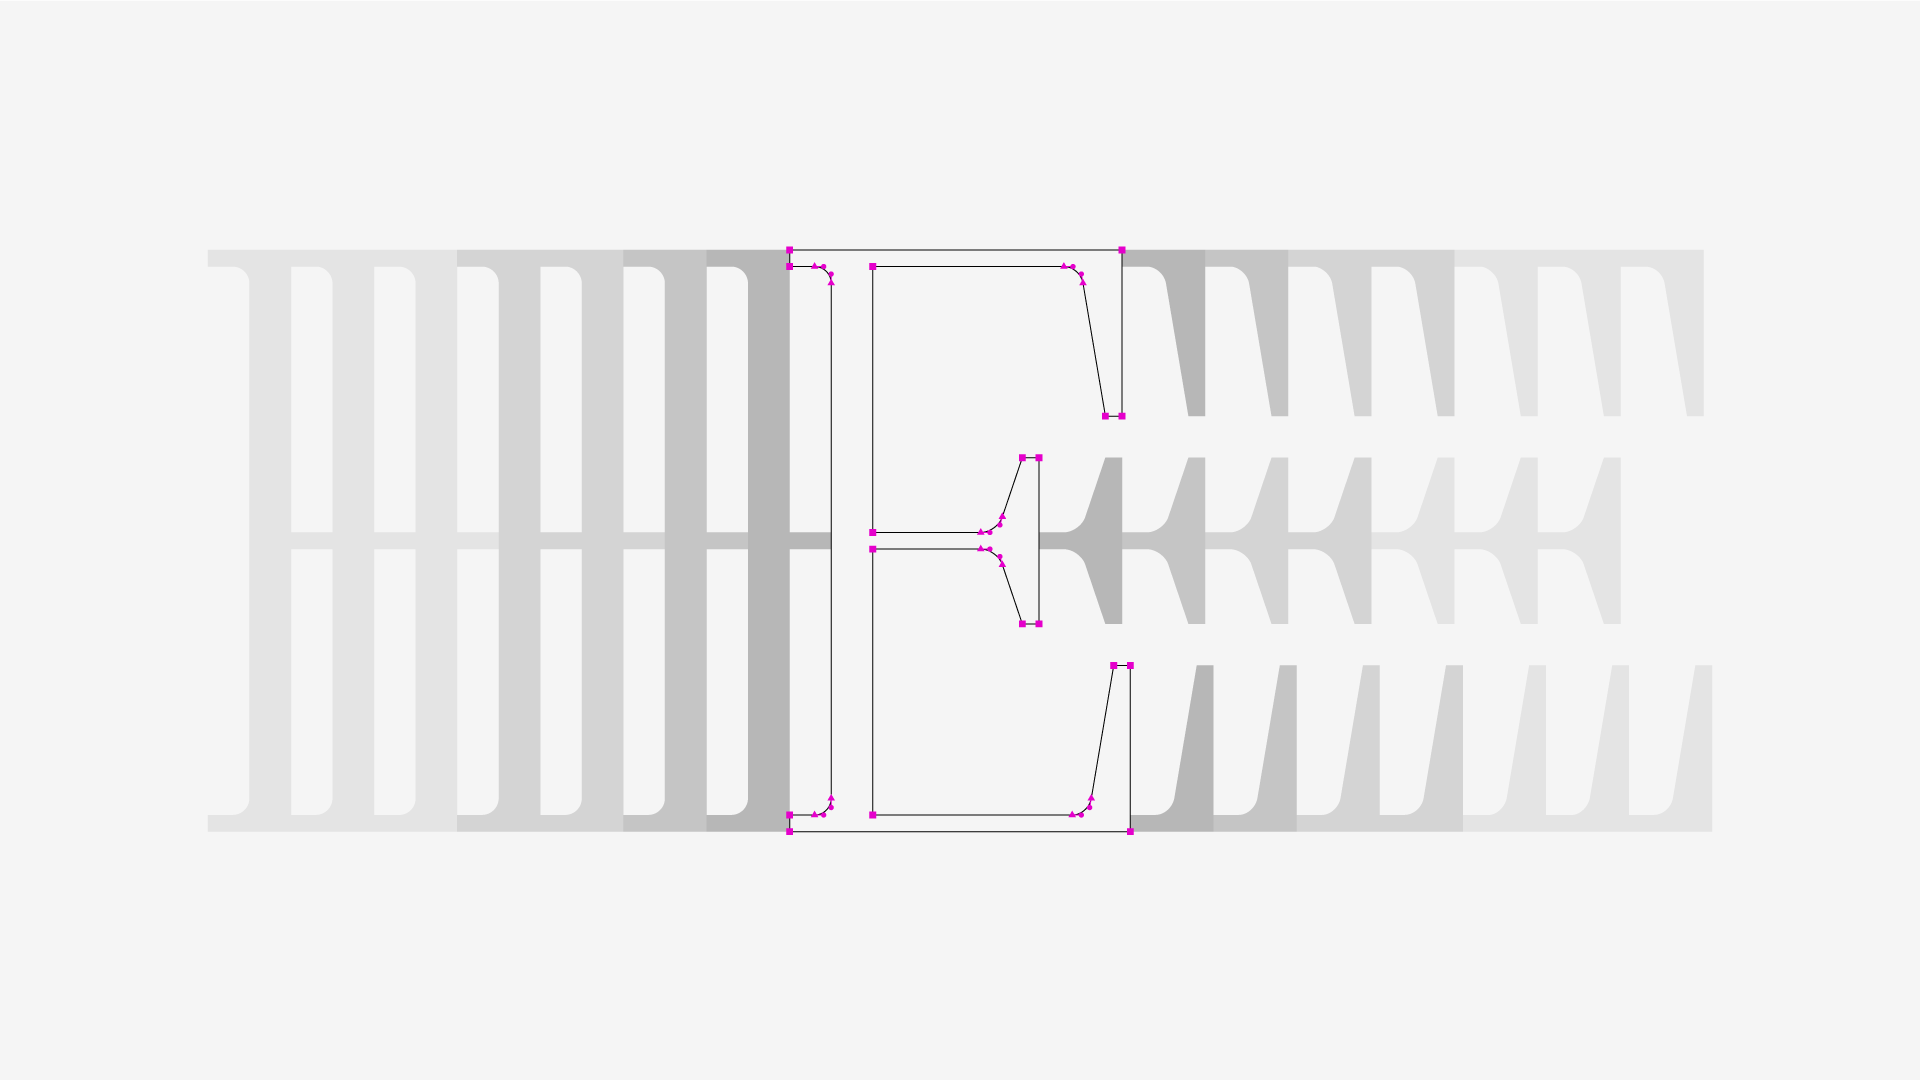
After we have the base glyph, the expansion is pretty simple.
Each glyph is divided in two components: one for the left repetition, another one for the right one. Have a look:
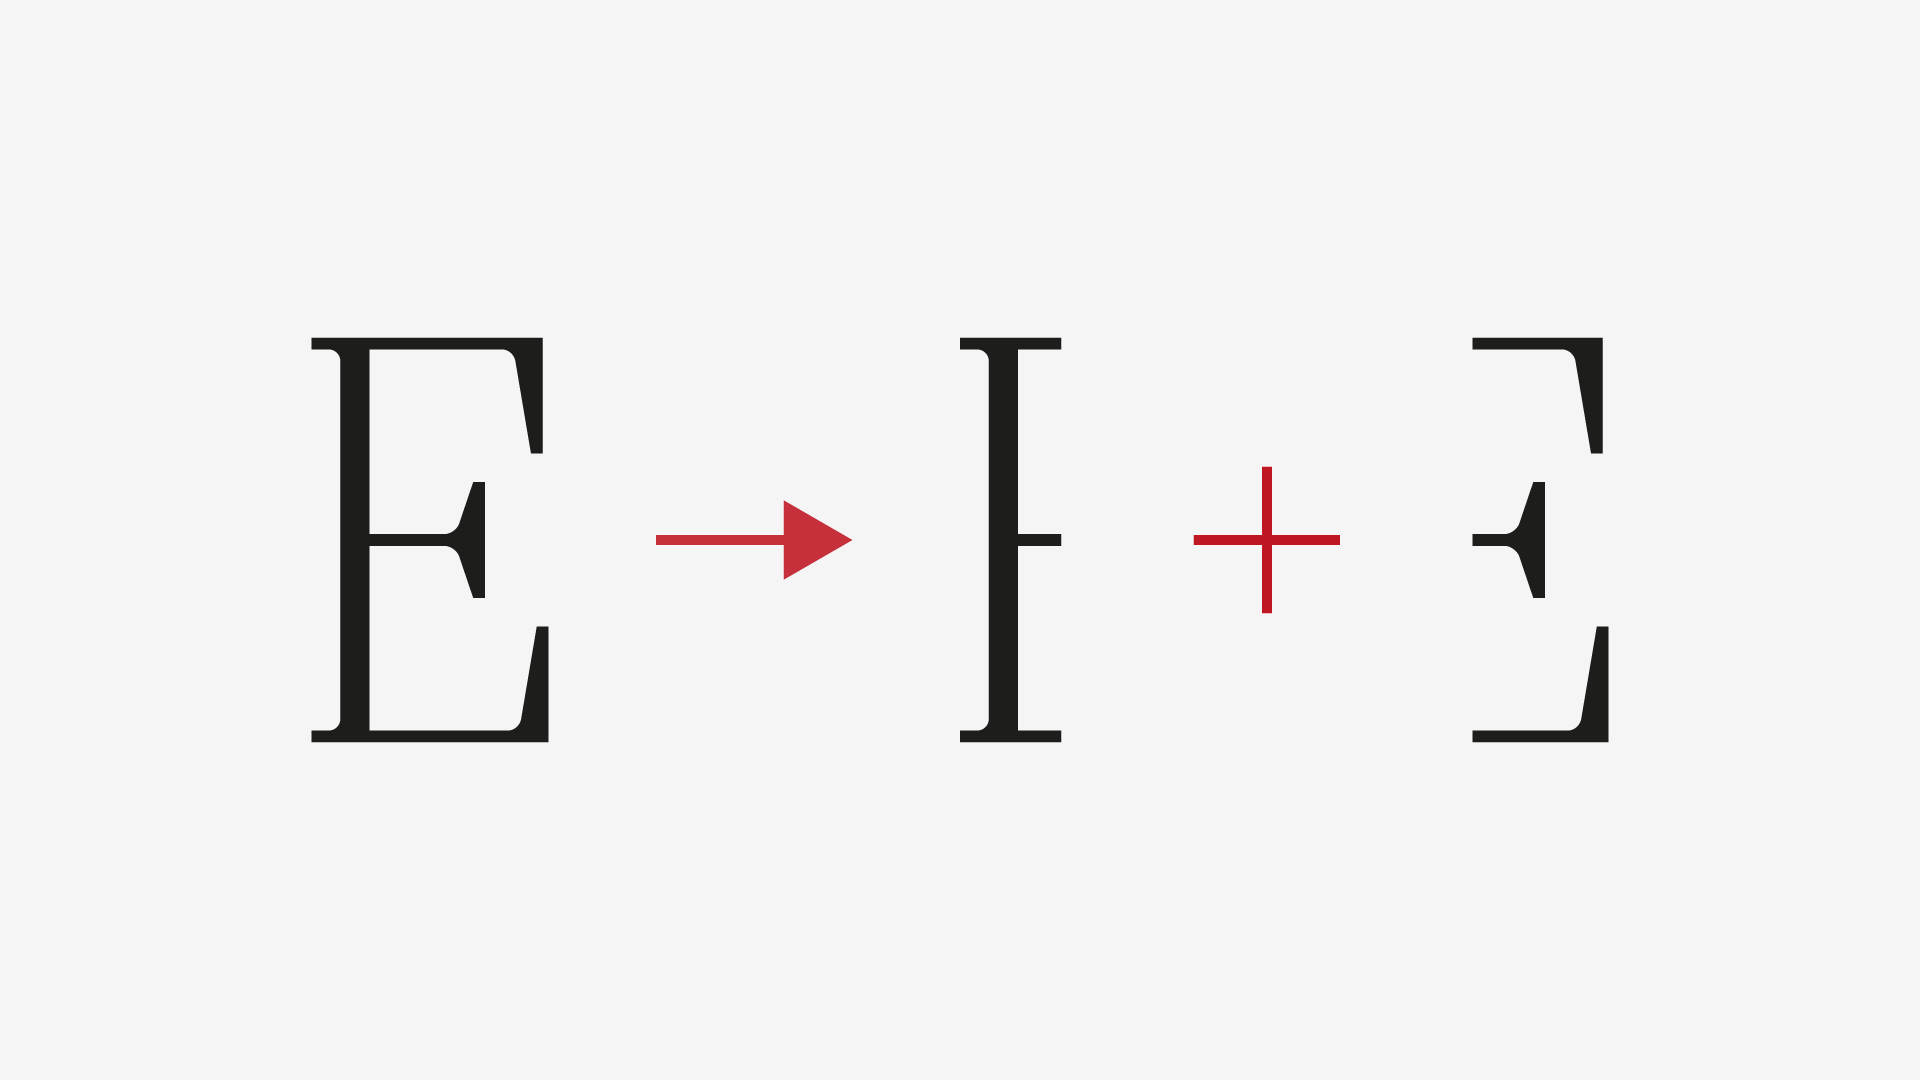
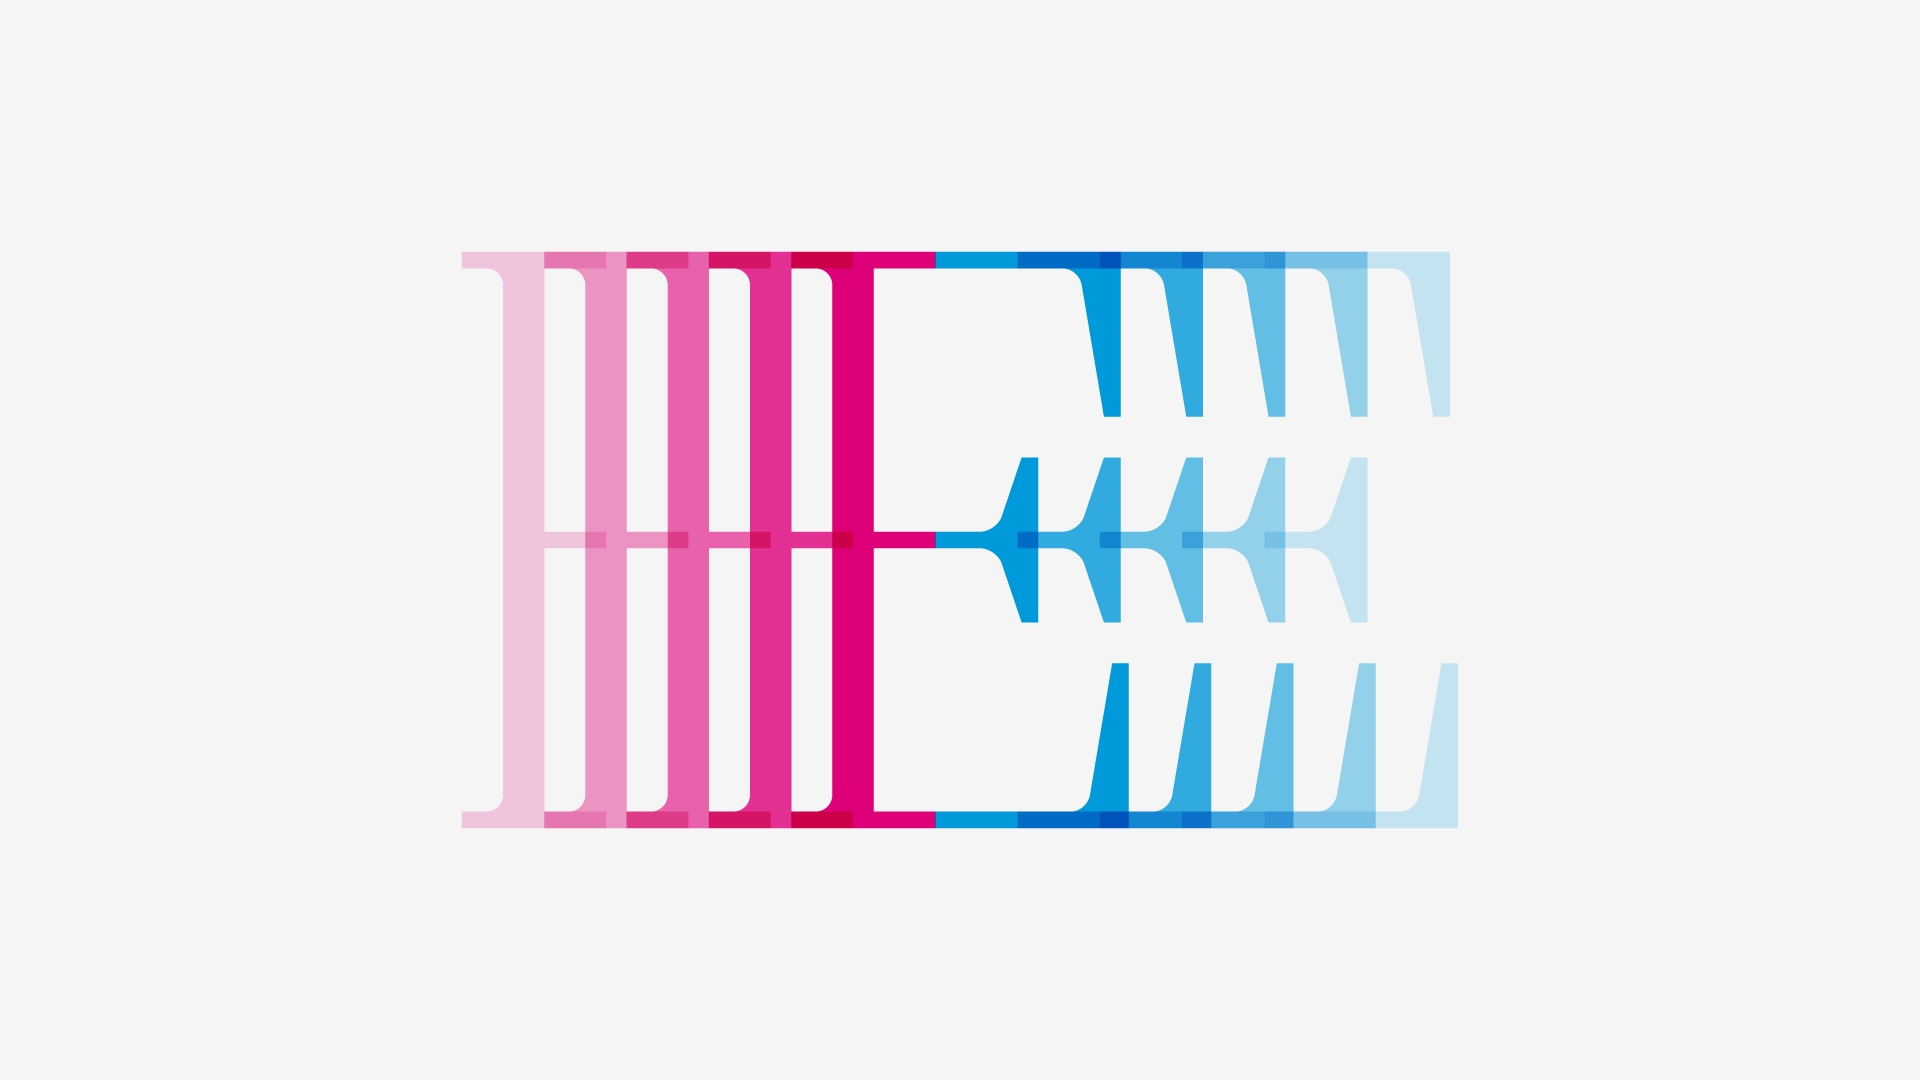
I’m sure you can tell where this is going now: the components are propagated, on top of the base shape, to left, right or both sides, and so we get the “repetition” styles:
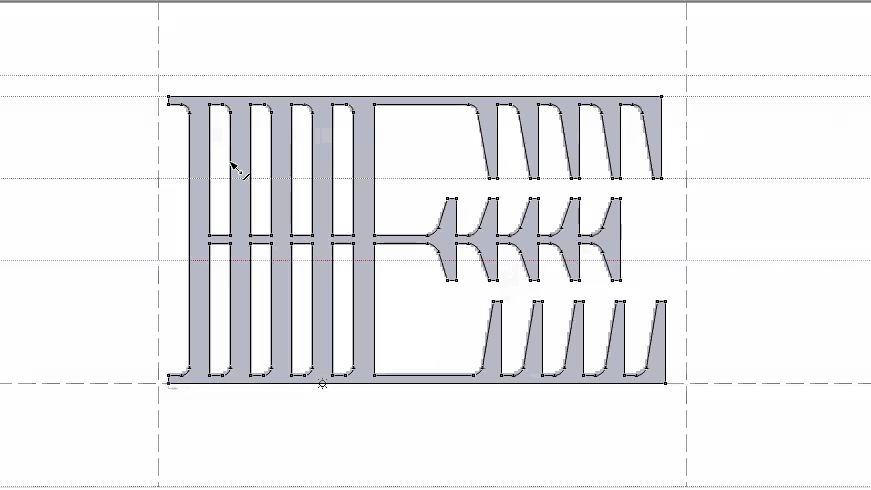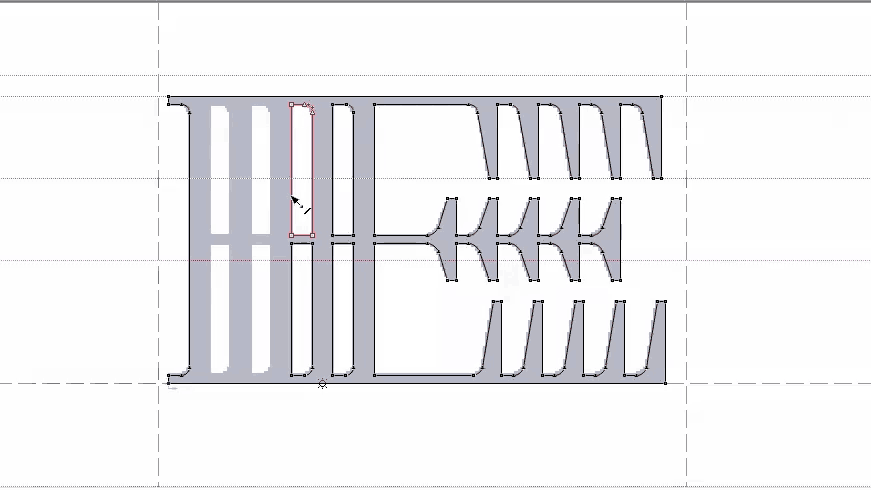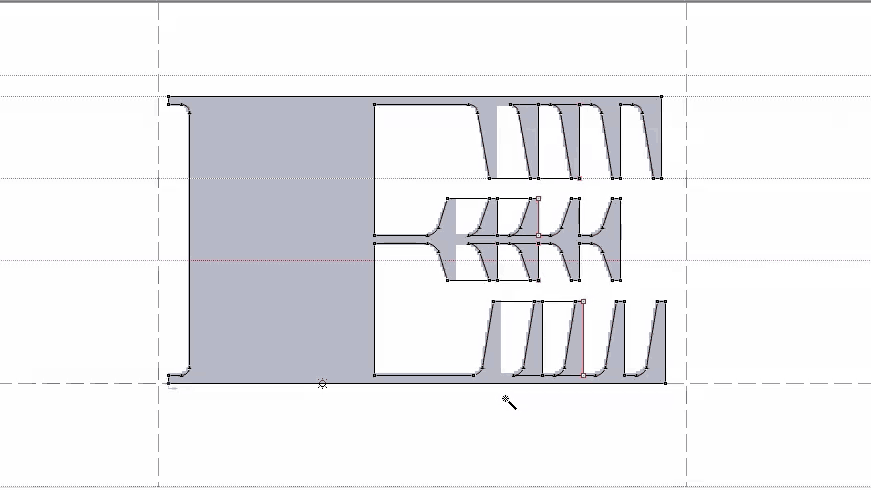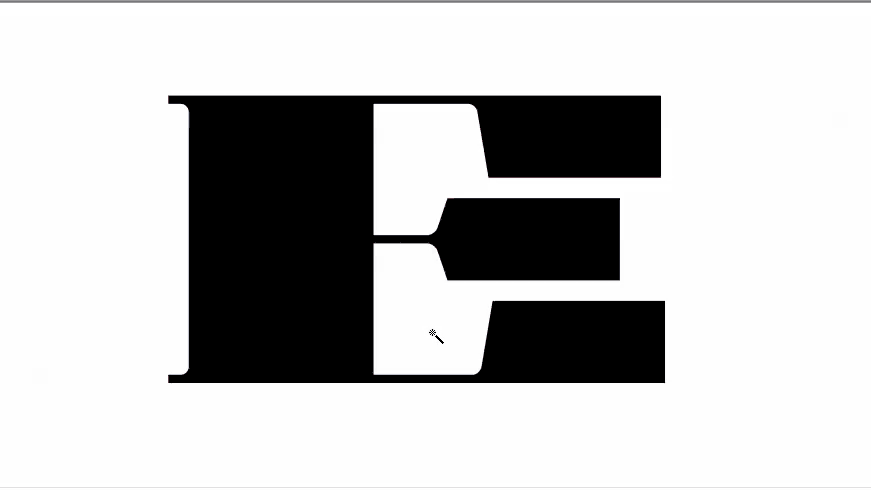
For the “expanded” set, we take the corresponded “repetition” glyph and simply delete what’s not needed. Here’s an animation of the process:
Et voilá!
4. The Math Of Going Overboard
As I’ve mentioned in the previous article, this font will be Latin-only. So, how many glyphs will it have?
I could go for a basic Type 1 Western/Roman character map (256 glyphs), but that would leave some languages aside. So, after the usual checking of language support tables, I’ve decided to go for the OpenType Latin Pro encoding (433 glyphs). If you think, as I do, that this is an OK character table, let’s make some further calculations.
Let’s consider a basic character map (Type 1 Western/Roman): 256 glyphs. As we saw on §2, we have something like 30 stylistic sets. Added with the default glyph, we have 31 variations of the same letter. How many glyphs are necessary for this? Here you go:
256 × 31 = 7.936
7936 glyphs. Ouch. And what about the OpenType Latin Pro?
433 × 31 = 13.423
Holy s***. Well, this might take a while.
But giving it a second thought, this font is all-caps, and that means that half of the alphabet is a duplicate. So, instead of 433 glyphs to draw, we have 310:
310 × 31 = 9.610
OK, this looks more manageable. *sighs*
5. Wrapping Up
This is all for today! I hope you’ve enjoyed the article!
If you’re a newcomer, be sure to read the previous post of this series an, while we’re at it, check the rest of the blog for some more juice! Oh, and don’t forget to subscribe at the bottom of this page, as well as to share it, if you think it’s valuable!
Thanks for your attention! Cheers!